
22 | Software Engineer Specialist Programmer - Infosys | Java React | Data Engineering | Agentic AI | Error Prone
Bengaluru, India
- Tweets 345
- Following 54
- Followers 54
- Likes 22


Pinned Tweet

Hello everyone !
I'm a 2026 grad and started my training as a Specialist Programmer at Infosys.
Alongside aiming to crack top PBCs, my stack has:
DSA & System Design
Data Engineering
Agentic AI
Java React
Looking to connect with fellow devs and grow.
Let's connect ! 🤝
1
4
176
update:
Finished python for data science: numpy and pandas in depth, dealing with different file types and data.
Done with machine learning, supervised and unsupervised from regression, classification to clustering, and some neural network basics.
Excited for upcoming GenAI 🏃🏻♀️
2
22
Back after a break👋
Over the last month I worked through PySpark, Kafka, Structured Streaming, ADF, Cosmos DB and Azure Databricks.
Lesson:
knowing how data moves (partitions, shuffles, offsets, types of files) matters more than memorizing syntax.
#letsconnect #BuilInPublic
1
71
kafka only guarantees order inside a partition, so the key you pick really matters.
checkpoints are what let a streaming job resume after failure and a bad cosmos db partition key = hot partitions + big RU bill
Key: Topic, brokers, partitions, replications, producers, consumers
1
1
37
Have been sharing my learnings consistently and had massive daily connections but got flagged for "inauthentic behavior" of no where, loosing my connections and that's where I wonder how this algorithm is working.
If anyone has beaten this glitch, let me know how to fix it?
@X
1
36
This week was all about Apache Kafka and PySpark Streaming!
Covered continuous data flows and how live streaming data is processed via chunks in unbounded tables.
It's crazy how apps like Uber, X handle massive data streams and deliver details in fractions of ms.
#BuildInPublic
28
Day 35
Today I tackled a massive chunk of Apache Kafka. I started with Why Kafka ? to understand its architecture.
Then, I dove into the official Introduction to Kafka and analyzed an Implementation of a Case Study.
#100DaysOfCode #ApacheKafka #DataEngineering #BuildInPublic
1
1
50
Next, I broke down the core engine components:
Kafka Producers: How data is published to the system
Kafka Streams: Processing event streams in real-time
Kafka Consumers: How data is read and processed
Getting a clear picture of how real-time data flows!
#BuildInPublic #Kafka
1
1
41
Learnt how the records are stored in key-valye pairs , their immutable nature, logs stored in partitions with unique offsets and crazy how replications work and their sync i.e ire- in replica sync which help in fault tolerance.
I'll continue to dive deep into kafka tomorrow!
#X
1
24
Day - 34
Massive deep dive into Advanced PySpark internals today.
Covered enterprise-level cluster security and broke down the Web UI execution logs.
Coded through complex problem statements using Core RDDs, DataFrames, and Spark SQL to truly solidify the logic.
#BuildInPublic
1
1
29
Also spent time practicing python scripts to solve problems with optimal time complexity constraints.
Feeling confident enough to tackle any cluster data pipeline or algorithmic problem statement at scale right now.
#PySpark #DataEngineering #Python #BuildInPublic #letsconnect
1
23
Started my DP re-prep last weekend, but paused it because Bappa was home. 🙏
Back to data engineering grind this week with Advanced PySpark, but I'm resuming the DP revision this coming weekend to wrap up the topic completely and move to the next.
#DSA #BuildInPublic #connect
1
21
When the internet goes down but the grind can't stop.
Operating entirely in offline mode today, pulling up downloaded requirements and writing raw PySpark core logic in a plain text editor on the right.
No StackOverflow, just pure brainpower.
#CodingLife #BuildInPublic #connect

1
24
Locked in cloud and big data storage architecture:
• Cleared AZ-900 & DP-900 for Azure cloud foundations
• Mastered HDFS architecture and data types
• Learned distributed storage tools like HBase, Cassandra, and Mahout etc
#DataEngineering #BigData #BuildInPublic #letsconnect
2
50
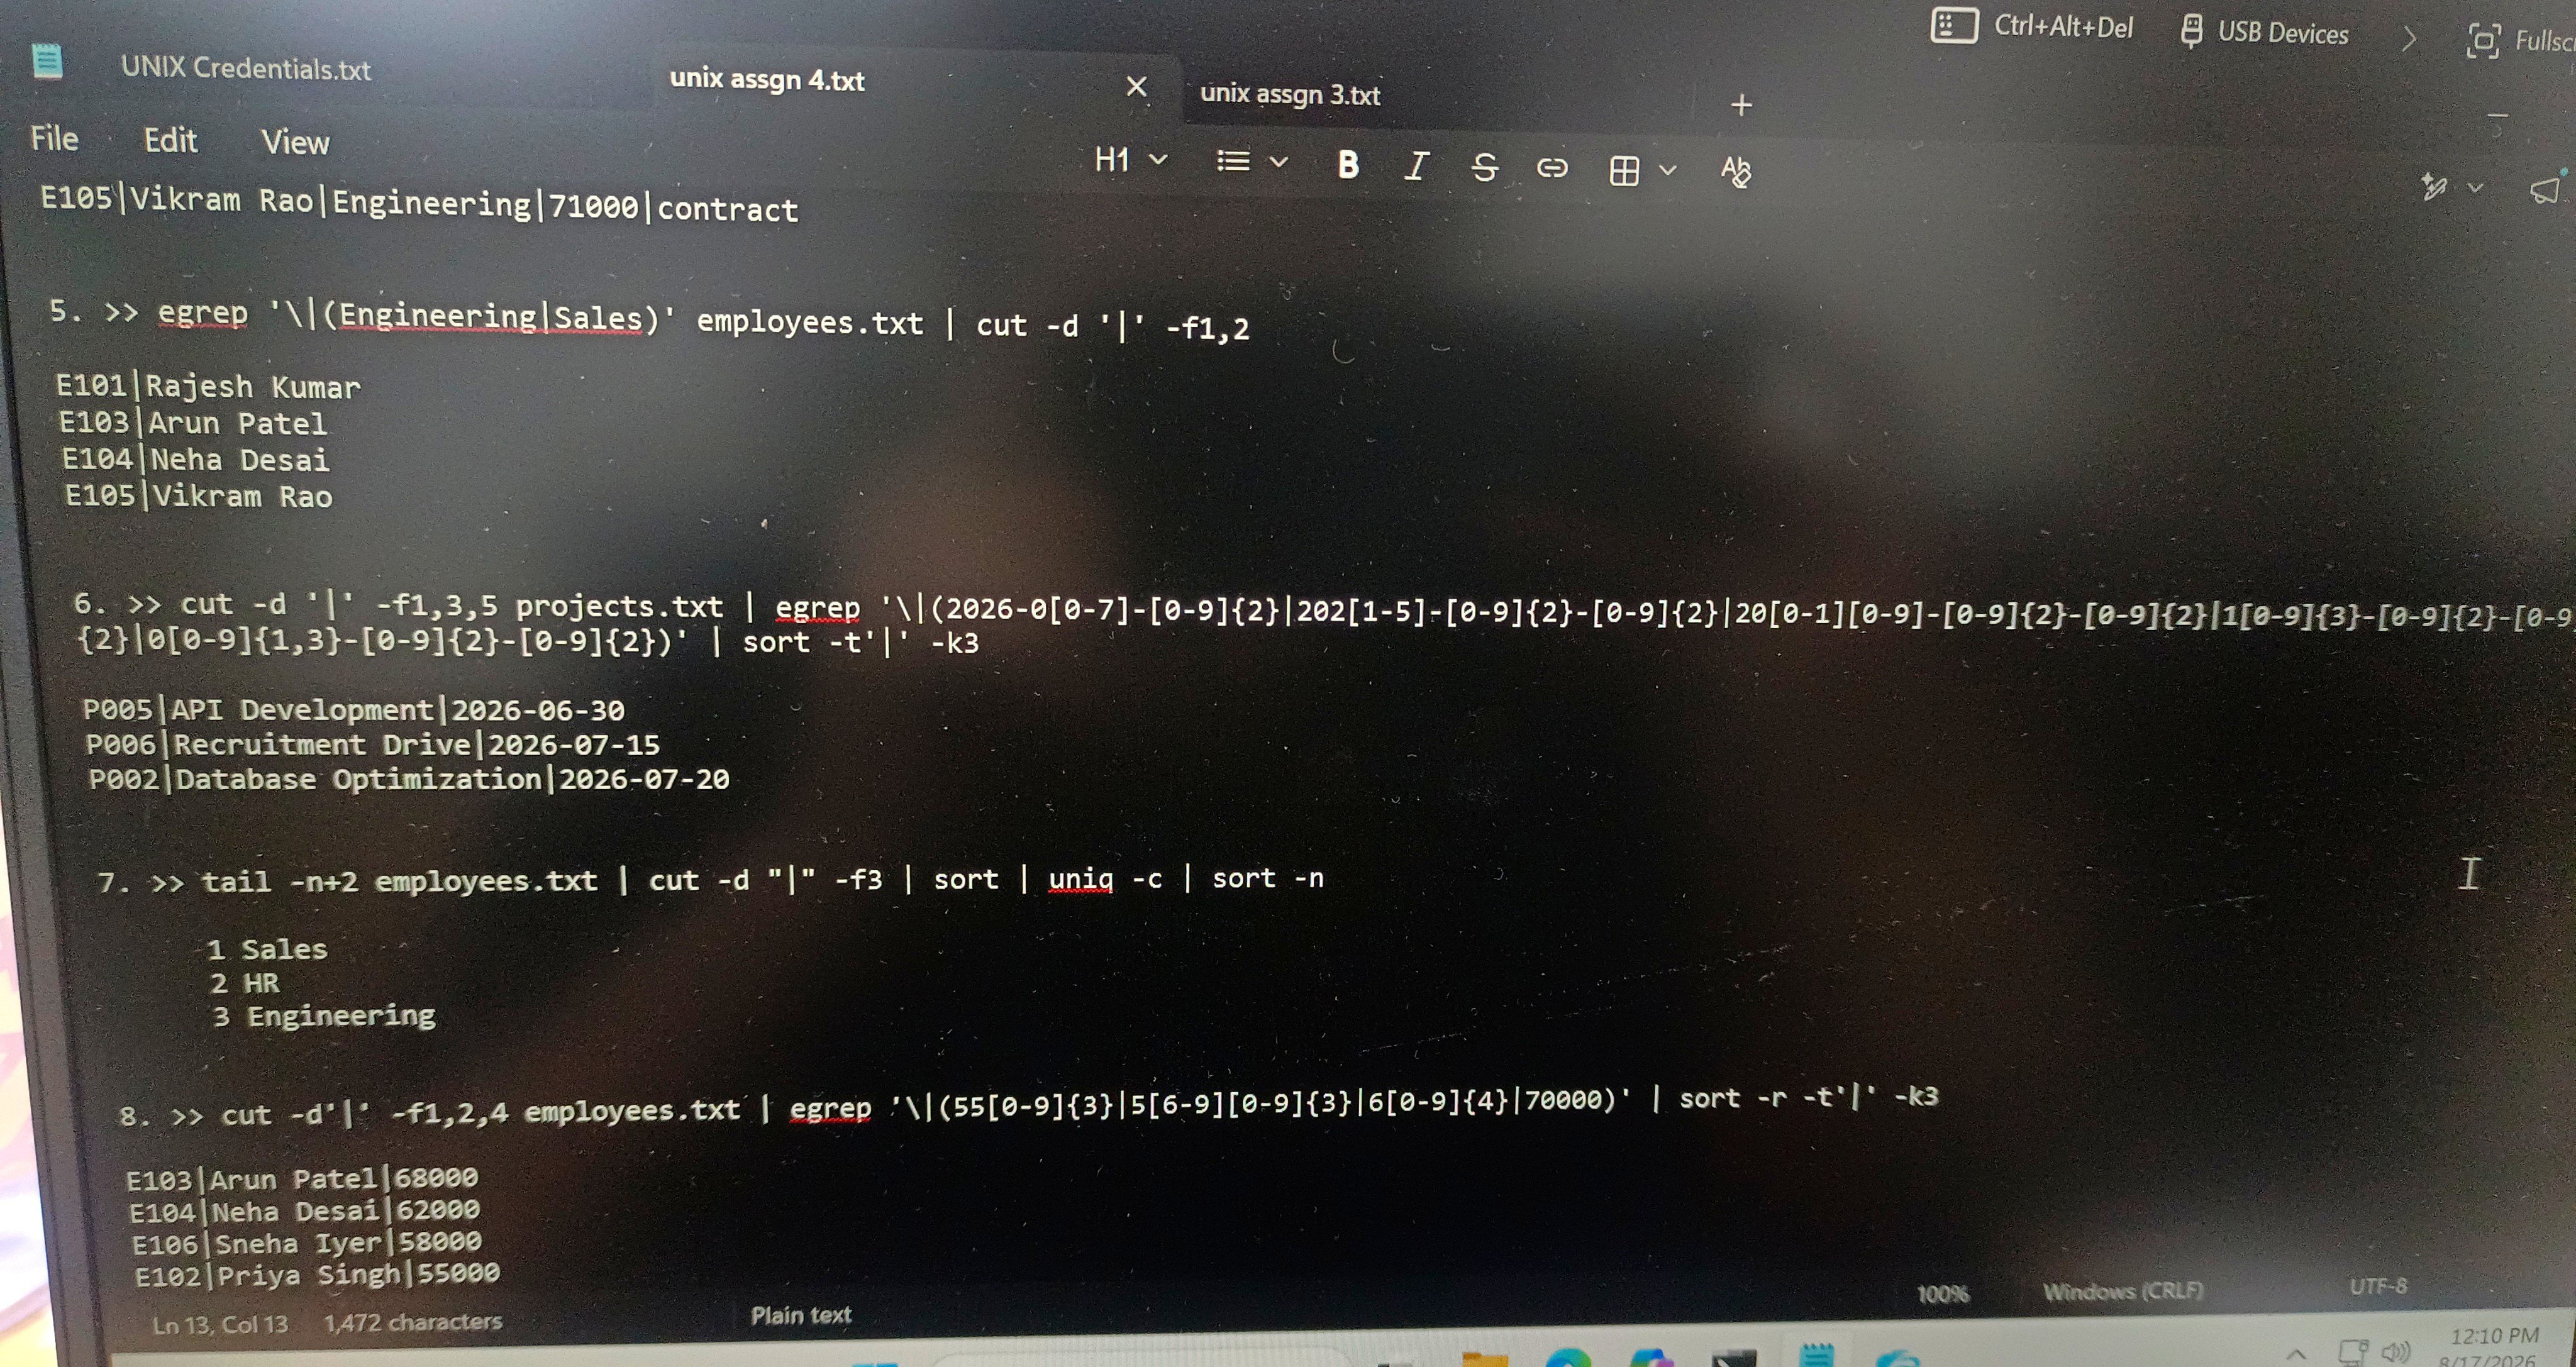
Before rushing into high-level big data frameworks, I made sure my foundational CLI skills were rock solid.
Spent time building complex Unix pipelines like combining grep, cut, uniq, and crazy egrep regular expressions to slice through raw text data.
#Unix #ShellScripting #X
1
4
51
From raw text files, I moved directly into NoSQL database internals with MongoDB.
Practiced handling nested document structures, writing complex aggregation pipelines, handling conditional arrays, and setting up indexing to keep queries lightning fast.
#MongoDB #letsconnect #X

2
33
Day 31 of my daily grind
Diving deep into Advanced PySpark internals today.
Shifted from basic operations to connecting external databases and writing custom cluster-level logic.
What I locked in:
• PySpark JDBC Connections & Connectors
• Custom UDFs & UDAFs• PySpark Web UI

1
3
54
Finished the session by exploring the PySpark Web UI to analyze execution stages and job DAGs.
Dealing with big data, knowing how to read the UI to see how custom code performs across the cluster is everything.
The data engineering grind keeps rolling.
#BigData #BuildInPublic
1
15
Last week I completely winded up LinkedLists, going from building the class from scratch to solving any problem on it.
This long weekend is all about the re-preparation of Dynamic Programming. Time to lock in and master the logic.
#letsconnect
#Java #DSA #LeetCode #BuildInPublic

3
45