

AI Architect & Builder - Inference, LLMs, SLMs GSoC Org Admin - Jenkins | Docker Captain | CNCF Ambassador
New Delhi
- Tweets 7,139
- Following 1,272
- Followers 8,364
- Likes 37,597


Pinned Tweet

What an amazing day! Presented a poster at @PyTorch Conference: how we optimised the RLM paper with pre-fix caching & batched Sub calls with @vllm_project
And a full house for our Pytorch Conference talk on running LLMs using Executorch on Android!


4
5
88
13,505
Shivay Lamba retweeted
Glad to be back at @AllThingsOpen after 2022! I am going to present a talk on how to improve security for running agents with @Docker Sandboxes - whether it is a coding agent or a multi agent system

4
4
47
995

Continuous sensing creates memory bottlenecks on edge devices. Qualcomm & @ramin_m_h, Co-founder and CEO of @LiquidAI are advancing on-device AI with Liquid Context on @Snapdragon — compressing multimodal inputs for fast, low-power execution.

5
10
48
5,656
So cool to see @MLHacks giving out some @arduino UnoQs as part of prizes for their AI hackathon at @AllThingsOpen 🙌

1
1
31
767
Shivay Lamba retweeted
How to cut coding-agent costs by ~78.5% using Jev to route between open models
All 32 selected coding tasks passed hidden tests.
Plus: Beam vs Muse Spark across 20 coding tasks - comparing cost, speed, and results 👇

12
5
40
2,718
Shivay Lamba retweeted

Don’t forget about #PyTorchCon next week! We’ll be at booth D6 and hosting these events:
🔷 Keynote: MAX and Mojo: The Best Way to Extend @PyTorch — 10/20 @ 9:35 AM PT bit.ly/4yn0R0J
🔷 Demo: Scaling AI Across Devices: ExecuTorch — 10/20 @ 1 PM PT
bit.ly/4yjrAeG

2
9
382
An AI coding agent becomes useful when it can investigate a problem, change the code, test the fix, and follow through to a working deployment.
That’s what I wanted to explore with the newly launched @reflection_ai Beam 🚀
Beam is built for coding, reasoning and agentic workloads. KubeTrace AI puts those capabilities to work on @kubernetesio incidents, with inference through @nebiustf.
The agent can:
→ Investigate logs, events and application code
→ Trace a failure to its cause
→ Propose code or Kubernetes manifest changes
→ Run regression tests in a sandbox
→ Build and deploy the repaired application
→ Check whether it recovered
The execution layer checks every proposed change against policy, and hidden checks decide whether the incident is resolved. You can inspect the evidence, patches, test output and failed attempts.

10
2
19
1,007
Eating consistently while traveling is hard. Especially when you’re managing fatty liver and trying to be more mindful of your food choices.
Airport meals, hotel buffets, unfamiliar menus, and another promise to “get back on track when I’m home.”
So I started building Tend, an AI nutrition coach for people who travel ✈️🥗
Tend is still being developed, but I built an open-source version of the meal-analysis experience called Mealsight so you can try the vision + voice workflow yourself.
The idea: show the assistant your meal, talk about it, and ask follow-up questions.
How it works:
→ Upload a food photo or describe what you ate
→ The vision model analyzes the image and identifies the meal
→ Review what the AI identified
→ A confidence check asks for clarification when the meal is uncertain
→ Continue the conversation with questions about your food
It runs on @NVIDIAAI Nemotron 3.5 Super VL through @nebiustf powering the visual understanding and meal-related responses. The part I find most useful is being able to move from a food photo into a conversation without manually describing everything on the plate.
@GradiumAI brings in voice 🎙️
→ Speech-to-text for describing meals and asking questions aloud
→ Text-to-speech for hearing the assistant’s responses
Demo 🎥
piped.video/watch?v=XgKR2wT7…
11
4
40
3,980
For people managing fatty liver, my goal is to make everyday food awareness easier to maintain while traveling, alongside guidance from their doctor or dietitian.
The meal analysis is something you can review and question. A photo alone won’t reveal every ingredient or exact portion.
The full Tend app is still in progress. For now, you can explore the open-source Mealsight version and build on it.
Code 👇 github.com/shivaylamba/meals…
2
172


Shivay Lamba retweeted

Muse Spark Open is on Nebius Token Factory from Day 0
It is the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Try it: tokenfactory.nebius.com/play…

8
13
204
403,778
Shivay Lamba retweeted

Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio

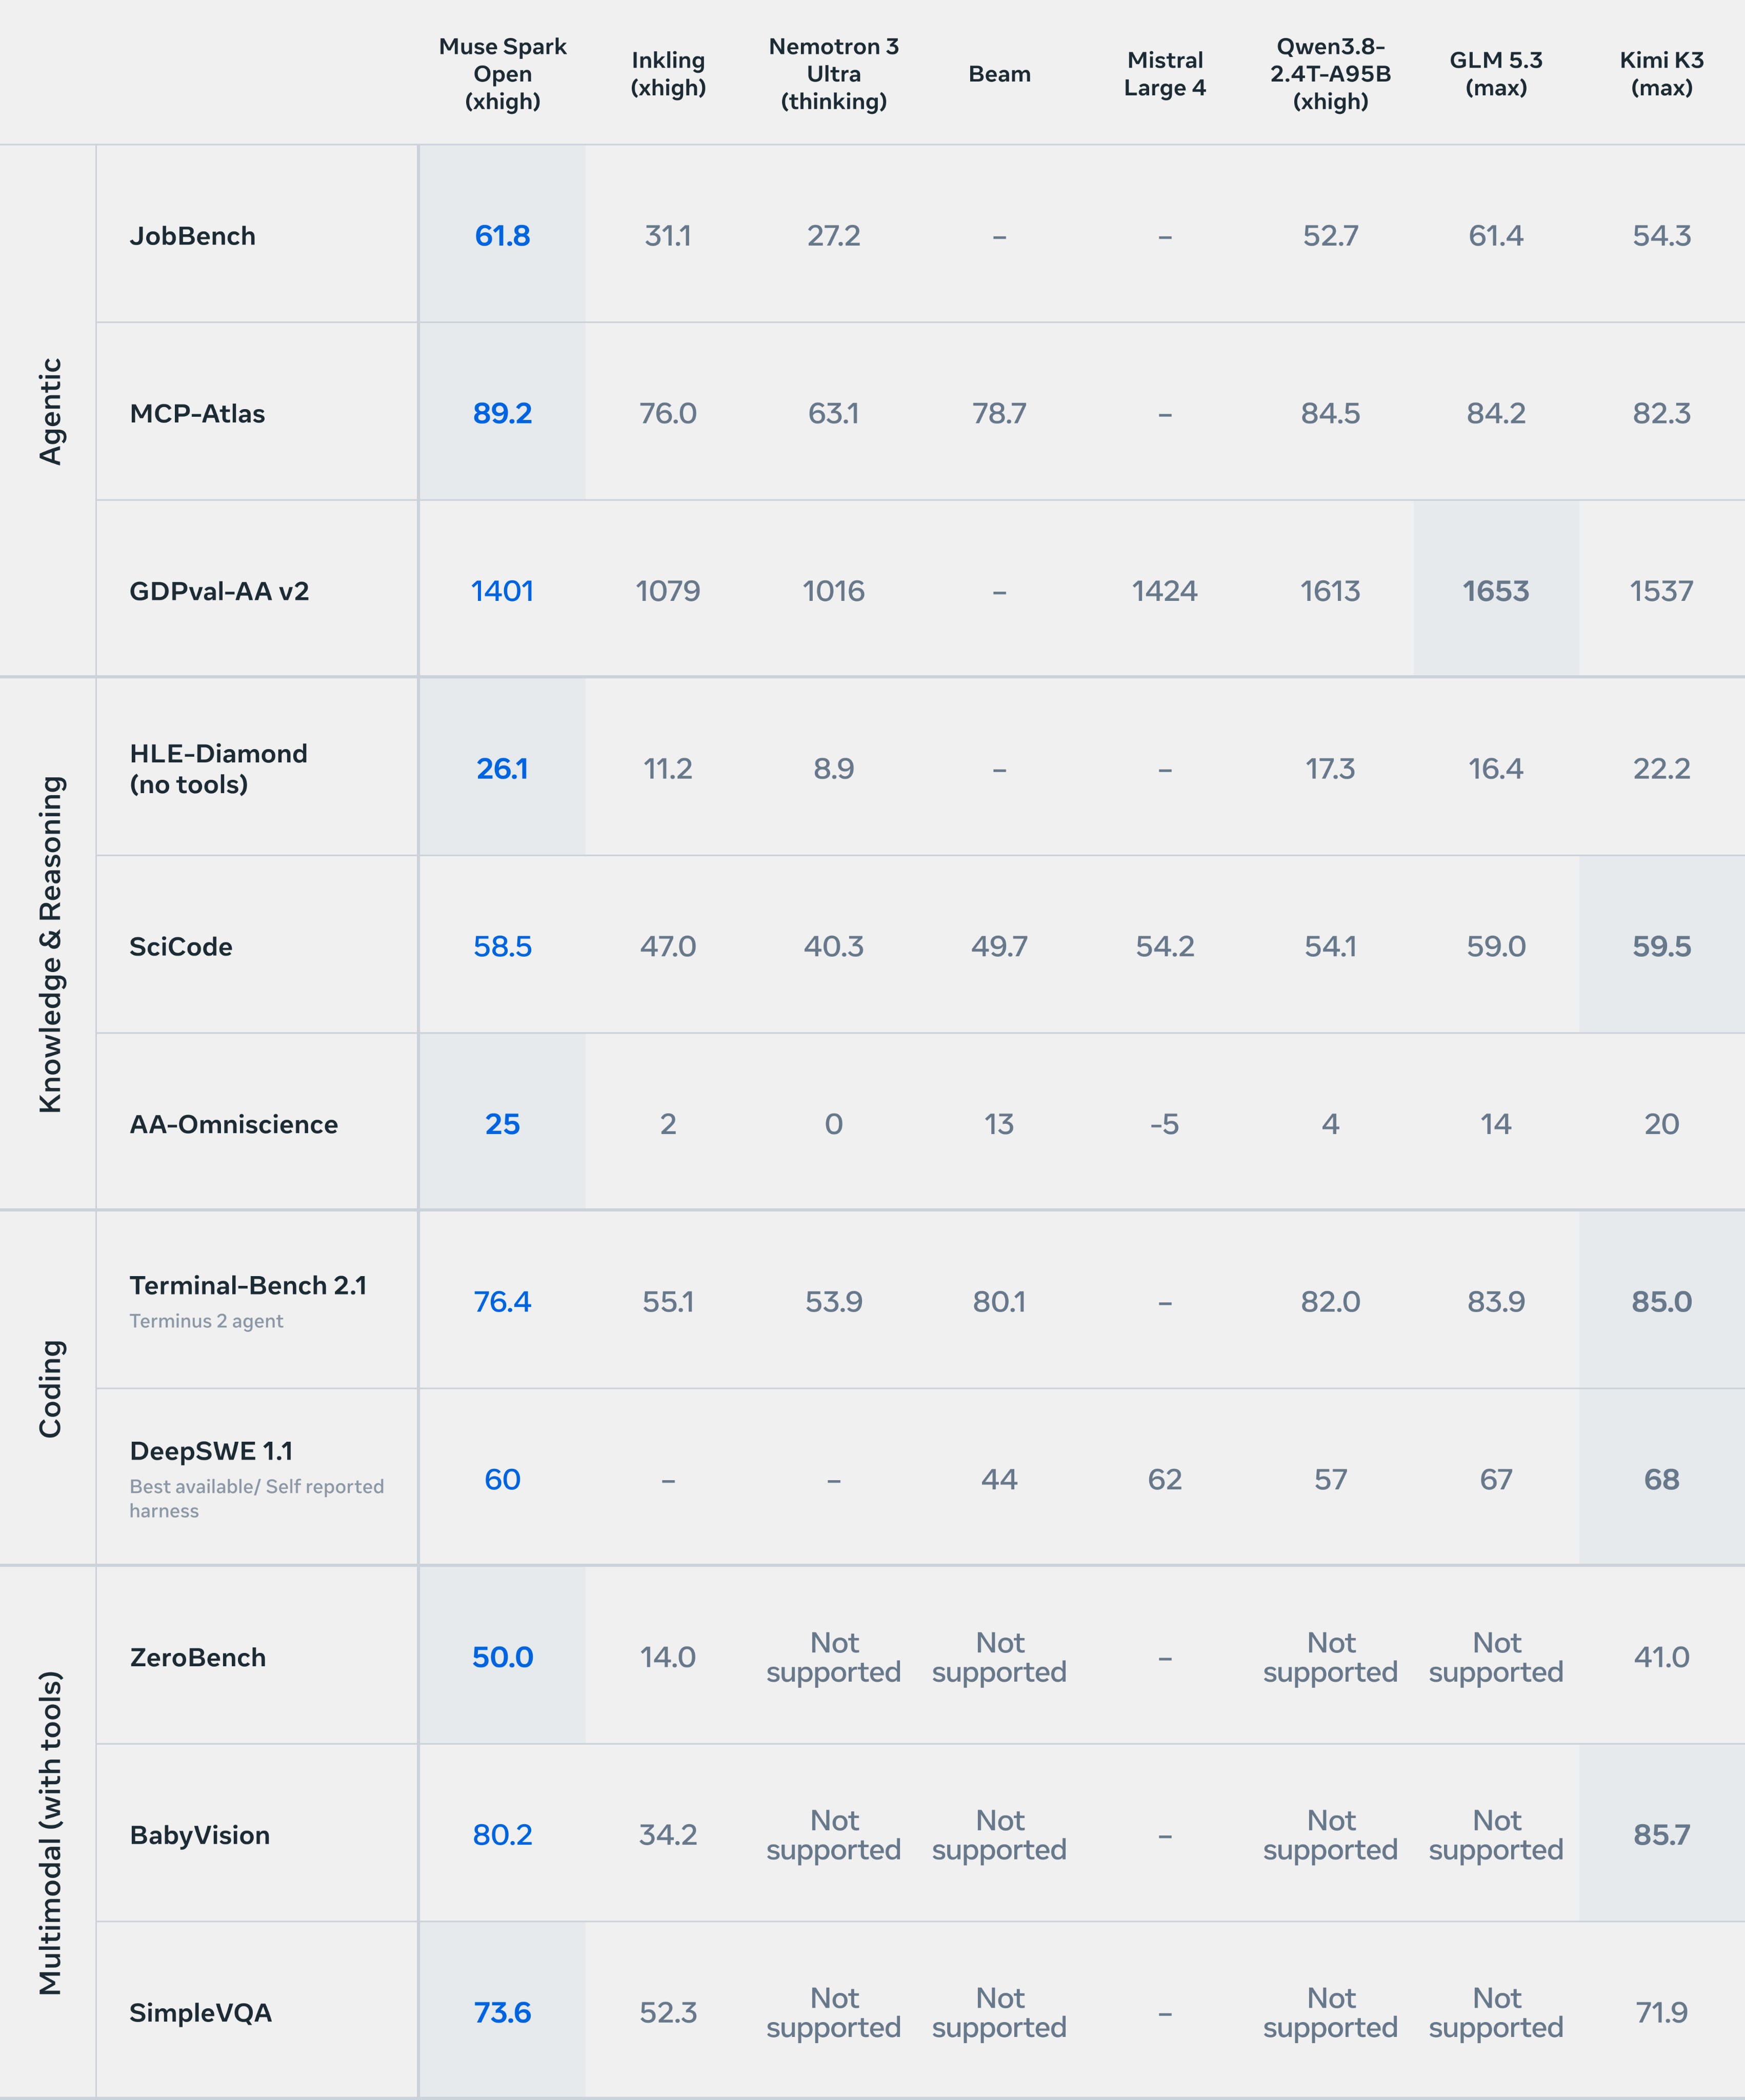
474
1,223
11,521
1,221,596
Shivay Lamba retweeted

Gemini 4 Argon is now globally available.
Built to solve your hardest problems from start to finish, the model brings frontier capabilities across coding, enterprise workflows, and cyber defense.

393
674
6,454
2,526,715


Shivay Lamba retweeted

Today we are rolling out Gemini 4 Argon globally in the Gemini API, to Pro + Ultra in Gemini App, and Ultra subs in Antigravity!
Argon is a huge step forward for Gemini, and a labor of love. This model has been battle tested by over 100,000 people at Google over the last month, with so much new innovation, ambition, and hard work baked into this release. The team has been heads down over the last 6 months working to make this possible across the stack (research, infra, safety, eng, etc).
We rolled the model out to cyber defenders as part of our fairwind program and early access customers over the last 2 weeks, it has been amazing to see and talk to folks who are now using this model daily. Seeing the models writing capability, raw knowledge and persistence for coding, paired with new features like 1M token output when the model needs to work more has gotten me even more excited about our path ahead.
This is just the start of the Gemini 4 era. As you saw with 3.5, 3.6, 3.7, and 3.8 Flash, our iteration speed with Gemini is fast : ) Now with Gemini 4 Argon to work from, I am cannot wait to see the progress continue, and most importantly see what this new model enables for the world.
This is such a special moment in the arc of technology, as millions of people everyday tackle problems they could never have thought possible before. Gemini 4 Argon was built to help you tackle the hardest problems. I have personally felt this spark with Argon and hope you do too. Onwards!!
1,248
769
10,976
1,093,464
Shivay Lamba retweeted
The problem with “YOLO mode” is that an agent can act with your access. A worktree won’t isolate your SSH keys, cloud credentials, or the rest of your disk.
Jozu Agent Guard puts the agent in a microVM, applies tool-call policies, limits network access, and keeps an audit trail.
I made this video with Opus 5.5 to show how the guardrails work 👇


9
6
20
1,215