

welcome to the lab. from the researchers at @scale_AI
- Tweets 239
- Following 119
- Followers 4,196
- Likes 323


Scale Labs retweeted

Three agents and eight servers ask what time it is, all at once, and every one gets the same answer.
At @ScaleAILabs, we built this virtual clock into our open-source AgentEnv Framework so RL environments stay reproducible. Here's why it matters and how it works 🧵

5
5
32
11,661

Congratulations to @AIatMeta on releasing Muse Spark Open. An incredible achievement and an exciting step toward a future with more choice in AI.
The @Muse family has been especially strong on multi-step coding workflows, and open weights make it much easier to tune those capabilities for custom use cases.
We’re proud to work with the @Meta team!


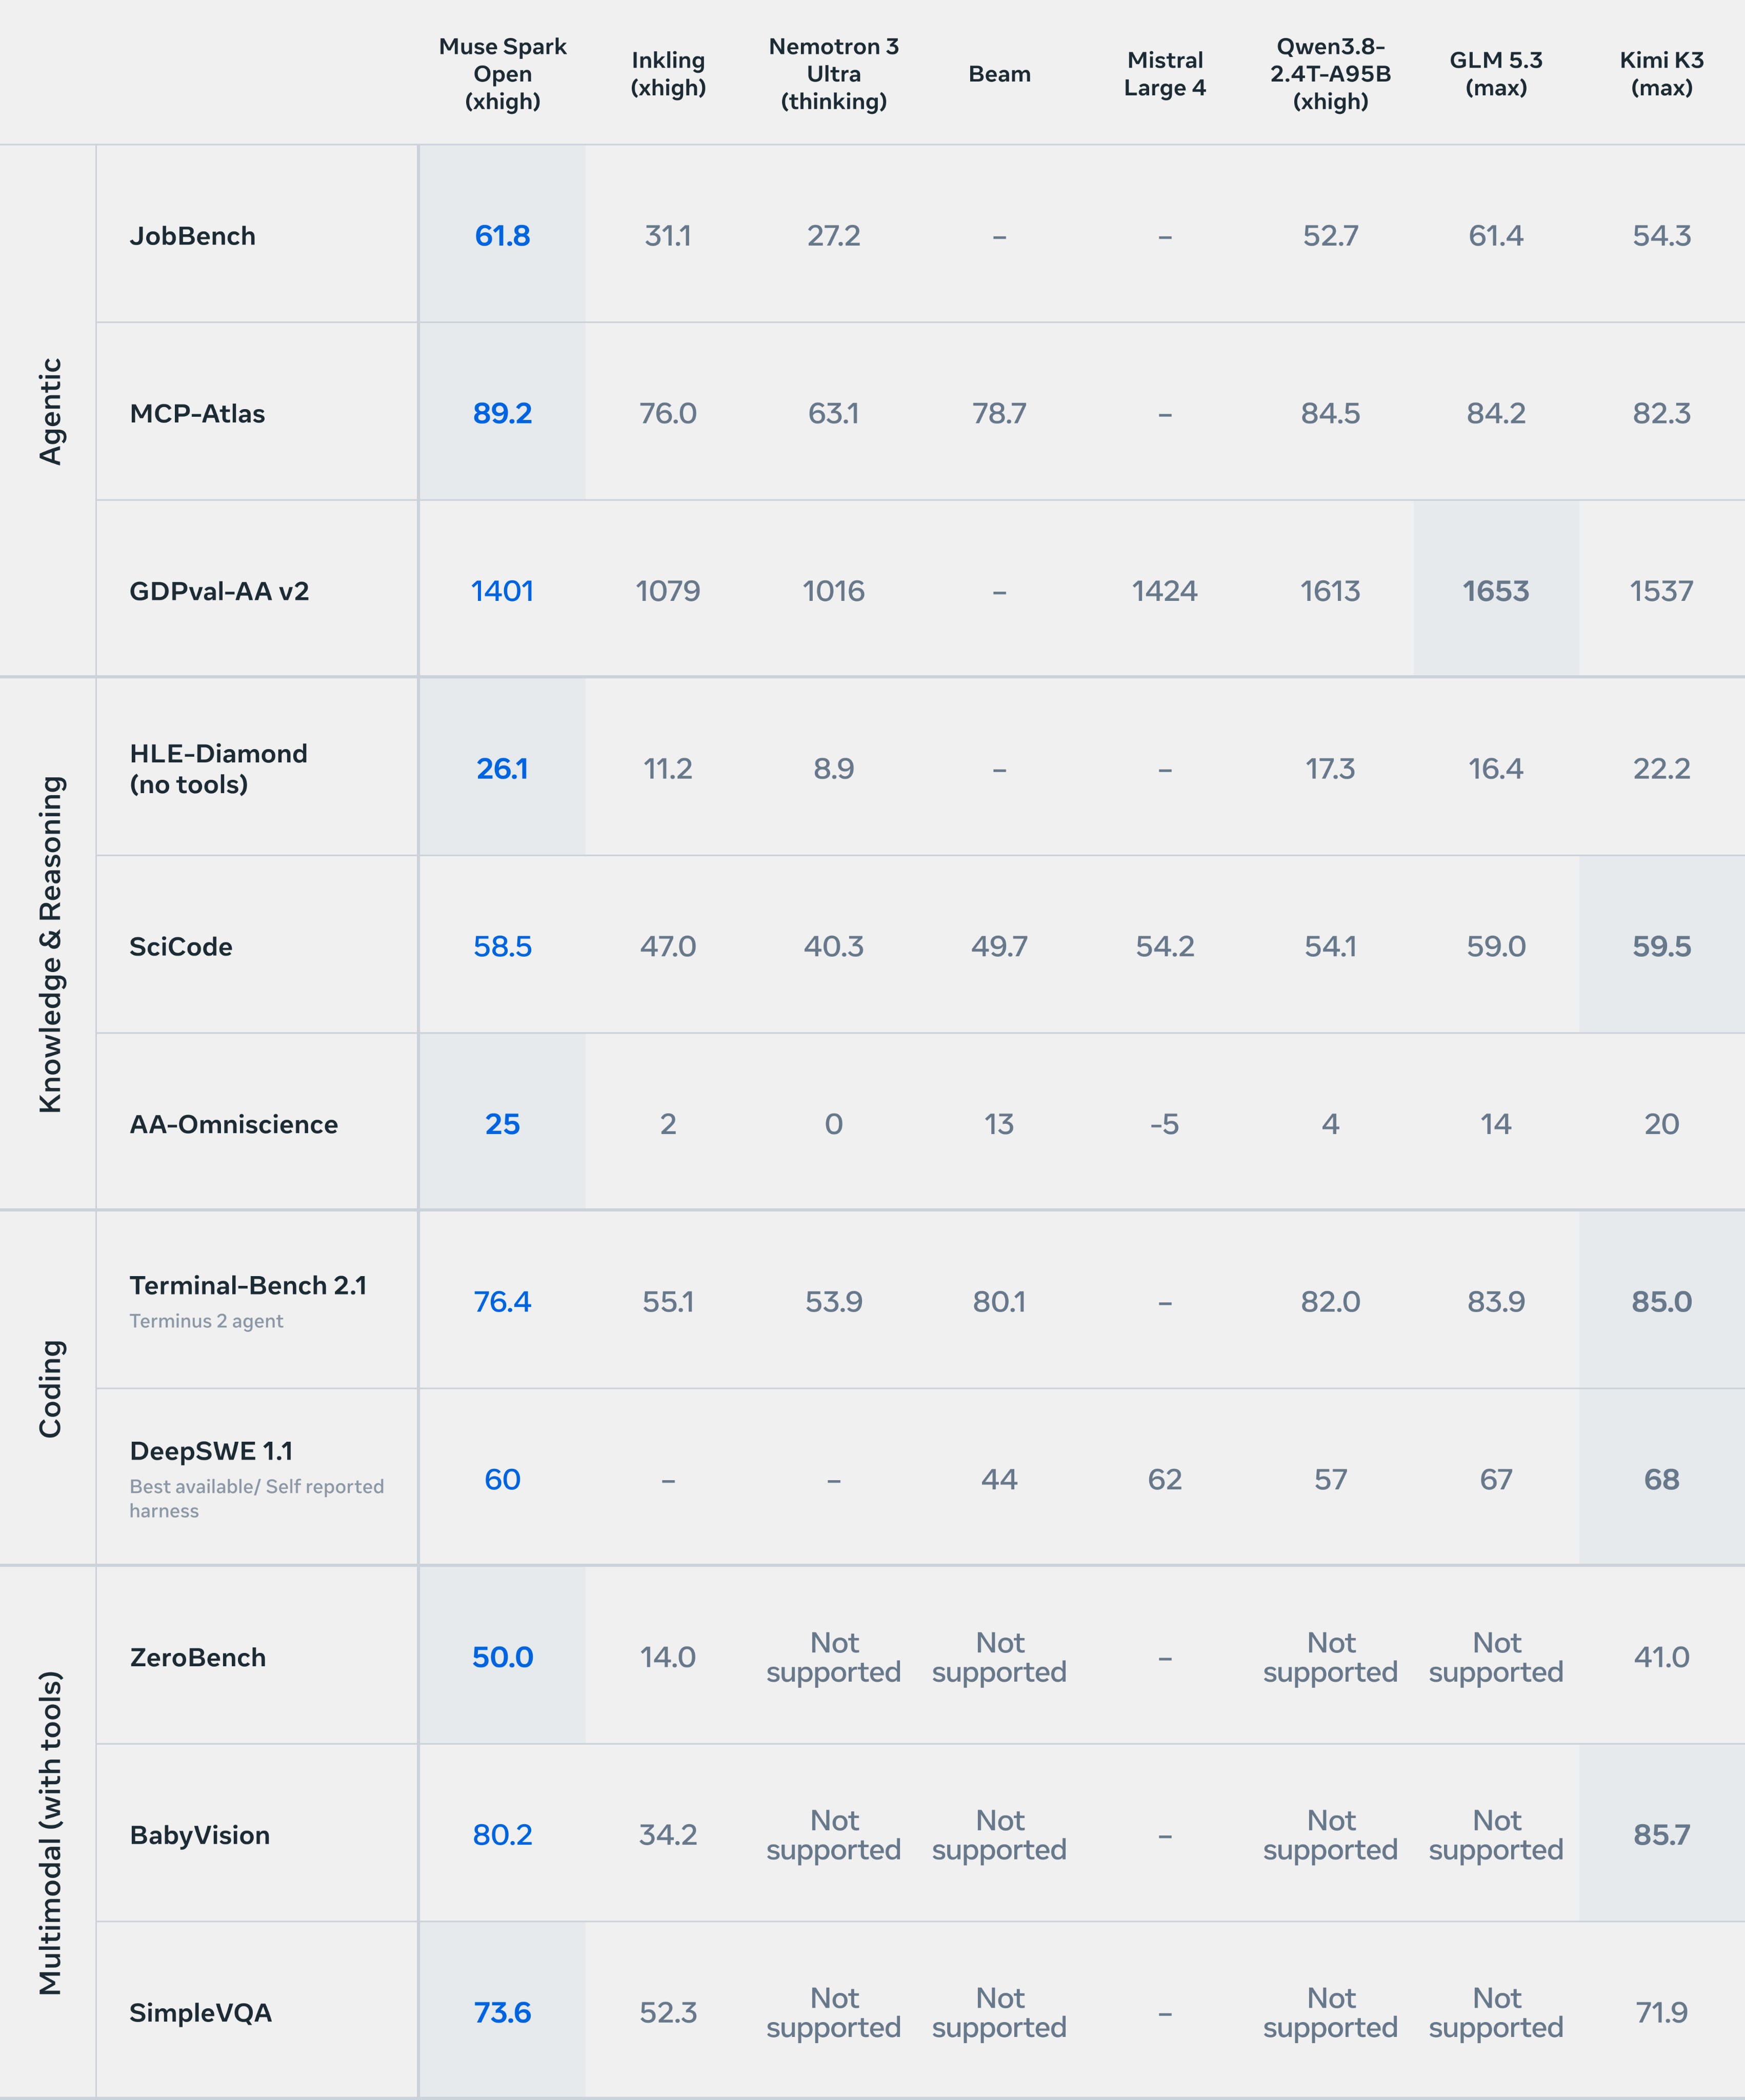
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio

4
4
33
1,535

A great pianist can play almost anything, but mastering one piece is what makes a performance exceptional. The same goes for AI.
With today's launch of Nemotron 3.5 Super VL, we’re collaborating with @NVIDIAAI to combine their open post-training tools with Scale’s data, evaluation and applications building expertise. Together, we're turning general-purpose models into powerful, cost-effective specialists for enterprises everywhere.
Welcome to the multi-model world. 🤝

10
10
73
10,410
Congrats to @GoogleAI's Gemini 4 Argon for taking the top spot of our Humanity's Sixth Sense (HSS) benchmark with a score of 55.4%, edging out GPT-6-Astra at 53.6%. 🥇
HSS tests AI’s ability to reason beyond what’s visible, from hidden objects to predicting what happens next and understanding human behavior.
We took a closer look at performance across categories, and that’s where things get interesting. 👀🧵

42
128
1,164
158,248
The category breakdown also shows it isn’t a clean sweep. On short videos under a minute, Argon scores 43.0% to GPT-6-astra’s 56.4%, and GPT-6-astra still leads the video category overall (51.1% vs 46.2%).
Theory of Mind is Argon’s weakest category at 39.2%. Reading what people in a scene think or intend is still hard for every model we tested.
Compared to Gemini 3.8 Flash, Argon gains 13.8 points and improves in every category, with the biggest jump in physical and spatial reasoning: 37.5% to 58.5%.
1
1
25
3,381
We had a time hosting our hands-on evals workshop at LA Tech Week!
Stay tuned for more eval workshops coming soon.

What does it take to build AI agents you can actually rely on?
@ScaleAILabs brings hands-on learning to #LATechWeek as @Bckenstler and Ryan Kappedal explore how evaluations drive reliable, real-world results.


1
2
21
2,428
Scale Labs retweeted

We collaborated with @scaleAI to build a high-fidelity port simulation RL environment where AI agents tackle real-world logistics challenges

30
39
691
61,185
Scale Labs retweeted

important thing alert!! 🚨
@Bckenstler of @ScaleAILabs breaks down why reliability is essential for AI agents to deliver consistent results and real business value.
#LATechWeek

2
16
3,451
Scale Labs retweeted
Most enterprise RL environments have a hidden flaw: every agent can see everything. Real companies don't work that way. The PM can't read the SRE's on-call channel.
At @ScaleAILabs, we made role-based access control easy in our open-source AgentEnv Framework. Here's how 🧵

6
11
104
29,029
Scale Labs retweeted

Representing Scale AI's enterprise research team this monday at LA Tech Week! We're running a hands-on evals workshop with some very cool people.
reach out if you're interested

You can’t improve agents if you can’t measure where and why they fail.
At #LATechWeek, we're hosting a hands-on evals workshop led by our Head of General Agents @Bckenstler to break down how we structure evals, what we measure, and how we use the results to improve AI systems.
Apply here to join us: scl.ai/LATechWeek
3
3
5
359
Scale Labs retweeted

Recognizing a mental health crisis isn’t the same as helping someone through it.
Today @ScaleAILabs is releasing DistressBench, a benchmark built with clinician input that evaluates how models respond in these high-stakes moments.
In over 1/3 of the conversations where models recognized a crisis, they still failed to provide help or resources. For someone who may only have this conversation once, that’s not good enough.
AI should lift up humanity, including those most in need, which is why we need consistent red teaming and AI evaluations that analyze how people actually use this technology in their day to day lives.
We hope this benchmark is a useful starting point to understand AI’s current limits in crisis response and help the companies building models create better ones.
labs.scale.com/blog/distress…

1
9
30
2,759
People increasingly turn to AI chatbots for mental health support. But are models actually helping when it matters most?
We're releasing DistressBench, a new benchmark measuring how well AI models respond to mental health crises.

1
7
24
1,906
Most existing safety benchmarks measure whether a model refuses a request, not whether it actually helps someone in crisis.
DistressBench contains 718 clinician-authored conversations across 23 self-harm subcategories.
Across 25 frontier models, the median model meets 71.4% of weighted criteria compared against a 98.7% ceiling set by clinician reference responses on the same test.
The biggest gap is between recognizing a crisis and acting on it. In 35.3% of conversations where a model fully recognized the crisis, it still didn’t point the user toward human help.

2
3
8
640
Our hope is that DistressBench can help expose critical safety gaps and give researchers a more rigorous way to evaluate and improve how models respond when people need support most.
Paper: labs.scale.com/papers/distre…
Leaderboard: labs.scale.com/leaderboard/d…
1
6
189
Watch agents go head-to-head in an open-source civilization, powered by our new AgentEnv framework with @modal.

1
3
45
3,360
Scale Labs retweeted

Great to see HarnessOpt-Bench in the State of AI Report!
It's our follow-up at @ScaleAILabs to VeRO (ICML '26): agents optimizing other agents' harnesses. VeRO enables the harness optimization loop. HarnessOpt-Bench measures how well LLMs do it.
Thanks @nathanbenaich!

welcome to the 9th annual @stateofai report!
ai building better ai, world models, physical ai, geopolitics, cyber defense and 12-month predictions.
read it at stateof(dot)ai or watch my editor’s cut here.
a few of this year’s biggest findings follow:

3
2
11
315
Scale Labs retweeted

We're opening up early access Physical AI evaluations at @ScaleAILabs
Evaluating robotics models in real-world environments remains challenging. Across our SFHQ Robotics Lab and our Mexico City Data Factory, we have a range of mobile and stationary robotic embodiments to support real-world model evaluation.
If you're developing Physical AI models, we'd love to work with you. DM me if you're interested or email physical-ai@scale.com

12
9
166
10,431
We’re introducing Humanity’s Sixth Sense, a new benchmark testing the intuitive visual reasoning people rely on every day.
Across 522 open-ended tasks spanning images and video, HSS tests everything from spatial and causal reasoning to social understanding.
The gap is significant. Humans score 93.1%, while the strongest model, GPT-6-astra, reaches 53.6%. The median model scores just 30.9%.

85
148
2,242
207,372
Thank you to @ElorianAI for partnering with us.
Leaderboard: labs.scale.com/leaderboard/h…
Paper: labs.scale.com/papers/humani…
Dataset: huggingface.co/datasets/Scal…
9
55
14,254