

Product + Growth @HuggingFace 🤗, the #1 open platform for AI builders. Co-founder Stupeflix (acquired by @GoPro).
San Francisco
- Tweets 4,494
- Following 709
- Followers 5,627
- Likes 8,317


How to use TPUs with Hugging Face models today: huggingface.co/blog/hf-torch…
64
Jeff Boudier 🤗 retweeted

Agent Manager is finally out!
Orchestrate dozens of agents across harnesses (Claude Code, Codex, OpenCode etc.) effortlessly.
Agents communicate and self-organize to help you achieve complex tasks and always keep running on HF spaces.
Try it: huggingface.co/spaces/lvwerr…

26
18
110
12,255
Silicon neutrality means freedom to choose your hardware.
With @awscloud , we're bringing native AWS Trainium support to 🤗 Transformers, Diffusers, TRL & Kernels through TorchNeuron.
Same PyTorch code. Familiar workflows. More choice.
huggingface.co/blog/hf-torch…

5
1
6
505
Before: custom modeling classes, a dedicated trainer, lazy tensors and static shapes.
Now: eager mode, torch.compile, FSDP and TP, straight through our libraries.
89% of the top 100 text-generation architectures run out of the box, up from 46%.
1
2
113
Your training script isn’t tied to Trainium. Your checkpoint is a standard Transformers checkpoint you can push to the Hub and load on any hardware.
Neuron kernels from AWS are on the Hub at aws-neuron/kernels, with up to 2.4x speedups on a ViT encoder.
That’s what silicon neutrality means for builders: choice without lock-in.
Huge thanks to the AWS Neuron team!
1
94
Jeff Boudier 🤗 retweeted

Hugging Face’s kickoff last night was absolute FIRE 🔥
A giant mega duck. DJs. Food, drinks, and music. Great conversations everywhere—catching up with familiar faces and making new connections. What a night. 🦆
Huge props to @jeffboudier and the @huggingface team for putting together such a stellar event! we missed you @ClementDelangue.
Today, the ExecuTorch Hackathon is in full swing at Founders, Inc., with teams building across three tracks:
💻 Compute — on-device AI on Snapdragon X Elite-powered Copilot+ PCs
📱 Mobile + XR — AI experiences on Samsung Galaxy S25 Ultra and Galaxy XR
🛠️ IoT — edge AI, sensing, and control on Arduino VENTUNO Q boards
From the dance floor to building on real hardware. Open Source AI Week is starting with a real bang—and we’re only getting started. 🚀
Hackathon details:
luma.com/executorch-hackatho…
Thanks to hackathon sponsors:
@AIatMeta @Qualcomm @github @open_intel_fdn @fdotinc @hackersquadio @PyTorch
#OpenSourceAIWeek #OpenIntelligence


2
4
30
3,403
Jeff Boudier 🤗 retweeted

What a night at Hugging Face's Open Together party in SF 🤗 1,000+ people celebrating open models!
Fun memory: back when Hugging Face was a tiny startup, I sat a few desks from them at Station F. Now they're the home of open-source AI. As someone who checks the Hub every day, being in a room full of fellow open-source fans was so exciting.


1
1
12
328


Jeff Boudier 🤗 retweeted

Friday night at @huggingface’s Open Together in SF. 🤗
Here to catch up on the latest in open-source AI and meet some of the people building it.
If you’re here, come say hi!
@_akhaliq where you at ?? 👀


3
4
38
5,214
Jeff Boudier 🤗 retweeted

2nd time @MiniMax_AI at the midway this week.
Caught up with some super amazing folks @ClementDelangue wish you were here
Thank you @open_intel_fdn and @huggingface for hosting.


4
1
16
725
Jeff Boudier 🤗 retweeted

I had an awesome time at the @huggingface party! I got to meet the 🤗 MCP maintainer @evalstate, dance with the 🤗 mascot, and meet 2 adorable microducks.

ALT Pamela, Shaun, and hugging face mascot
2
2
21
1,424


Jeff Boudier 🤗 retweeted

microduck and macroduck, at opening night HuggingFace party for Open-Source AI Week!


8
7
193
12,192
Jeff Boudier 🤗 retweeted

Chris and I went out for open-source AI and came home with matching hats. A little film from Open Together with @chrisstarrai.
Thank you @huggingface @arcee_ai @reflection_ai @PrimeIntellect @Dell for keeping things open and bringing us together.

1
1
4
182
Tonight is the night. Today is the day AI Builders unite.
I hear MEGADUCK is coming. Will you?
Open Together, 6pm on 10/16 at The Midway, SF. Free.
luma.com/OpenTogether

5
7
48
11,432
Jeff Boudier 🤗 retweeted

Customers love choice!
@AIatMeta Muse Spark Open and @nvidia Nemotron 3.5 Super VL are now available on the Dell Enterprise Hub with @huggingface 🤗
dell.huggingface.co/updates/…

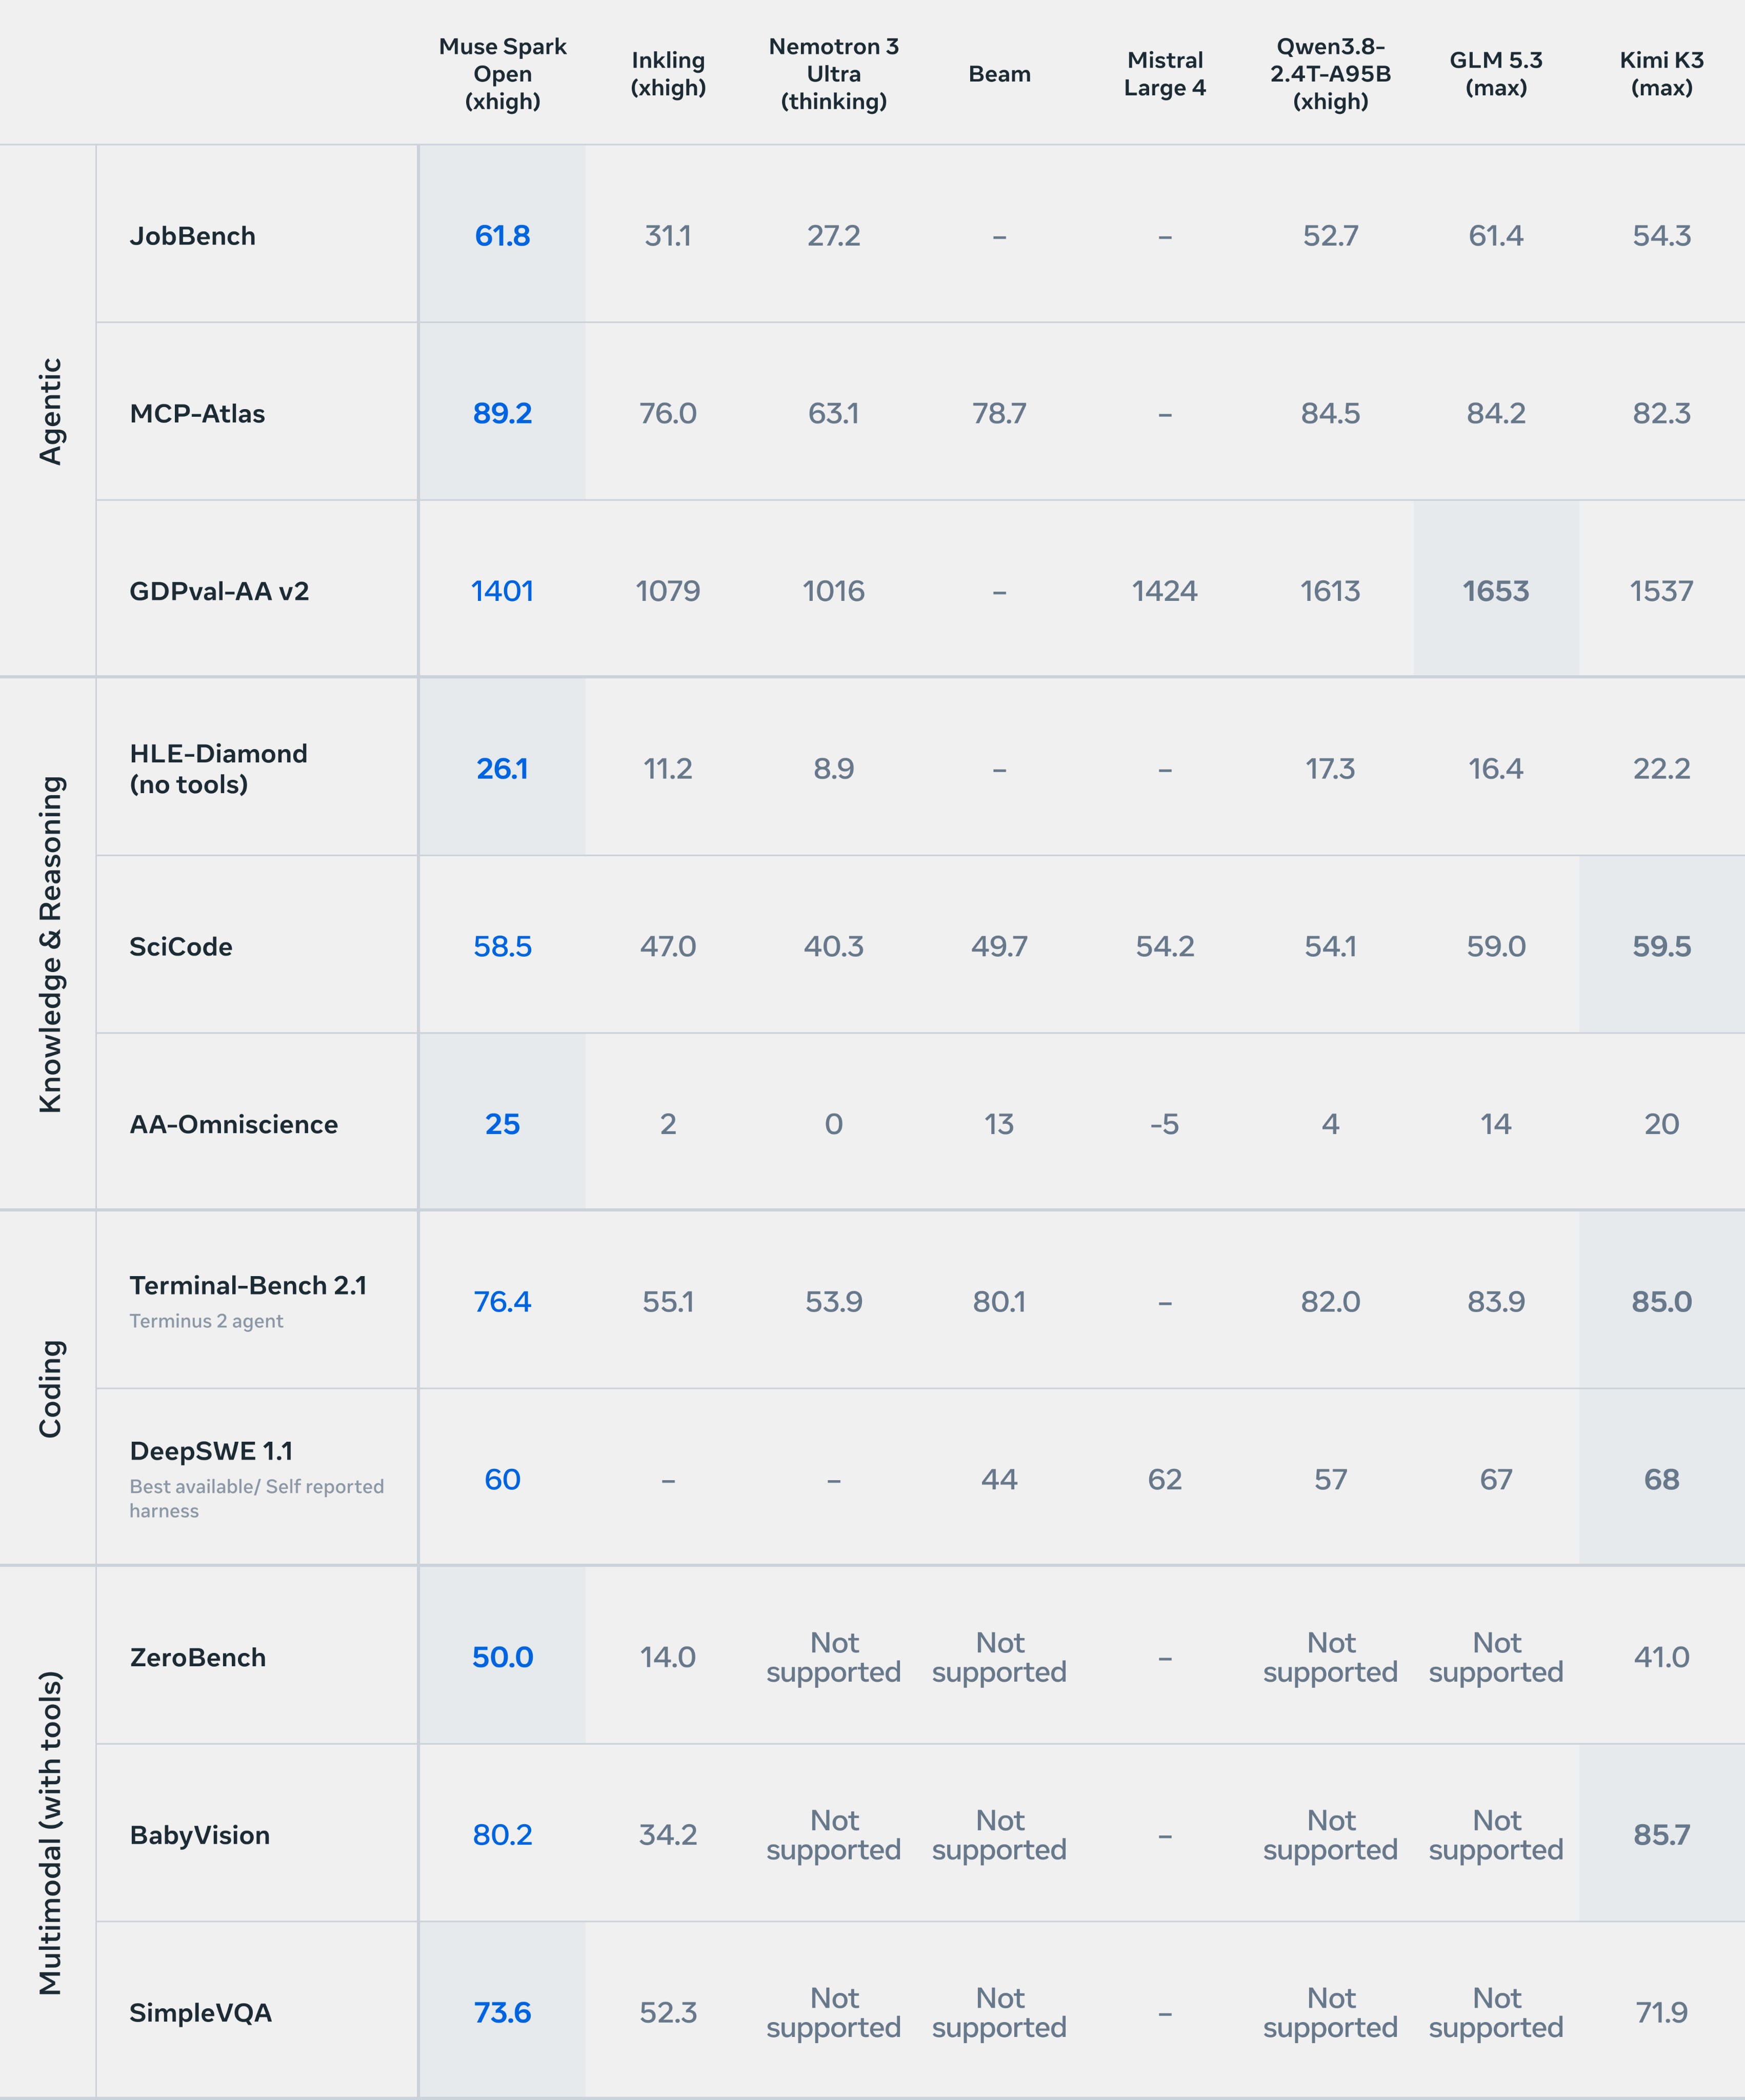
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio

25
22
149
41,766
Jeff Boudier 🤗 retweeted

Muse Spark Open is out, and TRL supports it from day 0 🤗
Fine-tune the 816B MoE (42B active) with SFTTrainer: transformers shards the model and splits the experts across GPUs at load time, and our example trains a LoRA adapter on 8 nodes of 8 H100s.

2
6
21
1,227
Jeff Boudier 🤗 retweeted

Open superintelligence is built in the open
Kickoff party for Open Source AI Week with @huggingface

14
19
197
20,062