

High-performance Rust-based vector search engine. discord.com/invite/qdrant
- Tweets 2,472
- Following 114
- Followers 13,694
- Likes 4,269




How is AI changing software development?
Qdrant's @EASzyszka joined @WeAreDevs at Agent Conf Berlin to discuss token usage, vector search, data quality, and the evolving developer workflow.
Watch the conversation:
piped.video/watch?v=CJa6YRq-…

1
1
Which German councils are discussing wind power?
Poliscope answers in one search.
4,800 council portals, 130M points, one self-hosted Qdrant node.
Searches went from up to 20 s to 0.87 s on average with hybrid search, tenant filters, and TurboQuant.
qdrant.tech/blog/case-study-…

4
4
26
Qdrant retweeted

The fine folks at @qdrant_engine are doing great work with Qdrant Edge to make vector search accessible on edge devices, such as the @huggingface Reachy Mini!
Great for memories, as they show below! Check it out.

What if your robot could remember your preferences, recognize your friends, and recall past conversations?
@ShuregDenisov and I built made a Reachy Mini remember with @qdrant_engine Edge, giving it local persistent memory.
Read how we did it 👇
qdrant.tech/blog/reachy-robo…

1
4
23
Qdrant retweeted

very happy to see Qdrant team testing our latest late interaction retriever!

21× smaller vectors. 99.9% of baseline retrieval quality retained with rescoring.
We tested Perplexity’s pplx-embed-v2-late with Qdrant’s TurboQuant across 4 ViDoRe v3 datasets.
856 KB → 40 KB per page, with a trade-off: rescoring requires the original vectors.
Full benchmarks below 👇

1
7
39
21× smaller vectors. 99.9% of baseline retrieval quality retained with rescoring.
We tested Perplexity’s pplx-embed-v2-late with Qdrant’s TurboQuant across 4 ViDoRe v3 datasets.
856 KB → 40 KB per page, with a trade-off: rescoring requires the original vectors.
Full benchmarks below 👇
8
15
131
Read the benchmarks: qdrant.tech/documentation/pr…
4
780 ms during background optimization. 4.3 ms after it finished.
Same Qdrant collection, very different search latency.
We tested 13 optimizer configurations on 1.76M vectors to understand the trade-offs between indexing, recovery time, and query performance.
Here’s what we found 👇

5
5
36
LangGraph docs: docs.langchain.com/oss/pytho…
Qdrant integration: pypi.org/project/langgraph-s…
3
Your AI agents need memory that lasts beyond a single conversation.
LangGraph supports long-term memory, allowing agents to store information and recall it across conversations. Now, you can use Qdrant as the storage layer with our new memory store integration.
Qdrant brings vector-native storage and semantic search to LangGraph’s memory system, so agents can retrieve relevant memories based on meaning, not just exact matches.
You can store user preferences, past interactions, and other useful context, then retrieve what matters when the agent needs it.

3
4
22
Take the free course on @DeepLearningAI today, and learn how to give your robots real memory with #QdrantEdge

This assistant remembers where you left your keys. No network connection. No remote server.
Build one yourself in a course built in partnership with Qdrant and taught by Dylan Couzon.
👉 Enroll for free: hubs.la/Q04zGYrF0
#AI #VectorSearch #AIEngineering

2
2
13
77× less vector RAM. 94.5% of baseline retrieval quality.
We got early access to Google EmbeddingGemma 2 and tested how far its Matryoshka-compatible embeddings could be compressed in Qdrant.
With shorter vectors + quantization + rescoring, we reduced the vector memory footprint by ~77× while retaining 94.5% of baseline retrieval quality.
Google also featured our work in their EmbeddingGemma 2 announcement.
Qdrant deep dive: qdrant.tech/blog/embeddingge…
Google’s announcement: blog.google/innovation-and-a…

1
6
50
Qdrant retweeted

We pushed 10M of Google's EmbeddingGemma 2 vectors from ~30GB of RAM down to ~0.4GB
float32, 768 dims: ~30GB
1-bit TurboQuant: ~1GB (99% nDCG@10 kept)
+ MRL to 256 dims: ~0.4GB (94.5% kept with rescoring)
77x less RAM for a ~5% drop in quality! TurboQuant + MRL is magic 🪄


Meet EmbeddingGemma 2, our first natively multimodal open model for on-device embeddings.
It expands beyond text to unify code, images, audio, and video in a shared space. 🧵
36
69
1,223
What happens when engineers are given a controversial topic and told to debate it?
We’re bringing something a little different to San Francisco Tech Week.
Join Qdrant × @neo4j for Hard Negatives: Engineers Debate Night on October 9.
We’ll put engineers, AI researchers, and builders into 1v1 debates on spicy topics like:
“Open weights should be banned.”
The audience votes live on who wins each round.
Plus, your RSVP includes food and one drink.
October 9 | 6:30–9:00 PM PDT
Spots are limited and registration requires approval.
Link: luma.com/sf-meetup-oct26

3
1
10
Lucy built a source-of-truth retrieval layer over 2.8M+ SEC and Korea DART filings.
Four hybrid lanes on Qdrant, payload filters applied inside the query, not after it.
94.7% Recall@10 on FinanceBench.
+0.160 answer accuracy from retrieval alone, with the answer model held fixed.
An open-weight model on Lucy RAG beat frontier models searching the web.
qdrant.tech/blog/case-study-…

16
2
36
/5
Constella is still a research preview, so there’s plenty more to explore around the quality/latency trade-offs and real-world workloads.
qdrant.tech/blog/constella-r…
2
/4
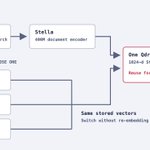
Nano and Zero are specifically trained to produce vectors compatible with Stella’s document embeddings. So you can switch between them depending on the trade-off you want between quality and query latency, without rebuilding the document index.
For example, Zero is extremely lightweight, while Nano is a small transformer that gets much closer to Stella’s retrieval quality.

1
/3
Constella takes a different approach here:
Documents → Stella → document vectors → Qdrant
Then, for queries, you can use different models:
Query → Stella / Nano / Zero → query vector → Qdrant
1
/2
Normally, your documents are embedded with a model and stored as vectors in Qdrant. When a user searches, the query needs to be converted into a vector in the same vector space so Qdrant can compare it with the stored document vectors.
The problem is that changing the embedding model usually means re-embedding your documents too.