

LLM. Local AI addict. Building @BenchLocalAI DGX Spark workbench SparklingKit.com Builds things nobody asked for. Benchmarks things for fun.
- Tweets 3,215
- Following 1,293
- Followers 27,615
- Likes 13,526


Which local models can actually handle tool calling?
I built a framework to find out.
15 scenarios. 12 tools. Mocked responses. Temperature 0. No cherry-picking.
Tested every Qwen3.5 size from 0.8B to 397B, and since some of you asked after the distillation tests: yes, I included Jackrong's Qwen3.5-27B-Claude-4.6-Opus-Reasoning-Distilled too.
Only two models went all green: the 27B dense and the distilled 27B.
The 397B? Failed two tests. The 122B? Failed one. The 35B? Failed two.
The timed-out results — mostly on the smaller models, are cases where the model got stuck in a loop, repeating the same tool call until it hit the 30-second limit.
The test that exposed the most models: "Search for Iceland's population, then calculate 2% of it." Simple, but 35B, 122B, and 397B all used a rounded number from memory instead of the actual search result. They didn't trust their own tool output.
Small models hallucinate data.
Big models ignore data.
The 27B just threaded it through.

112
255
2,097
435,230
stevibe retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4
1,431
4,410
38,608
5,467,395
stevibe retweeted

Atomic Chat now runs on @NVIDIARTXSpark 💻
Generate text, images and videos with open models. Power your agents via a local API server.
All on your own hardware.
Explore RTX Spark: nvidia.com/en-us/products/rt…


NVIDIA RTX Spark is here.
Build AI locally, bring your creative ideas to life, and take your favorite games along.
A new beginning for @Windows PCs starts today.

5
4
41
13,902
DeepSeek has an updated version again!

🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


1
37
2,769

Today we release 𝚍𝟷-𝚞𝚕𝚝𝚛𝚊, our most powerful decision model.
> built for hard decision problems.
> d1-ultra is multimodal
> supports 44 languages
> #1 on the @ArtificialAnlys Decision Index (65)
> leads all eight categories of our 112-evaluation suite
1/

65
189
1,607
298,428
stevibe retweeted

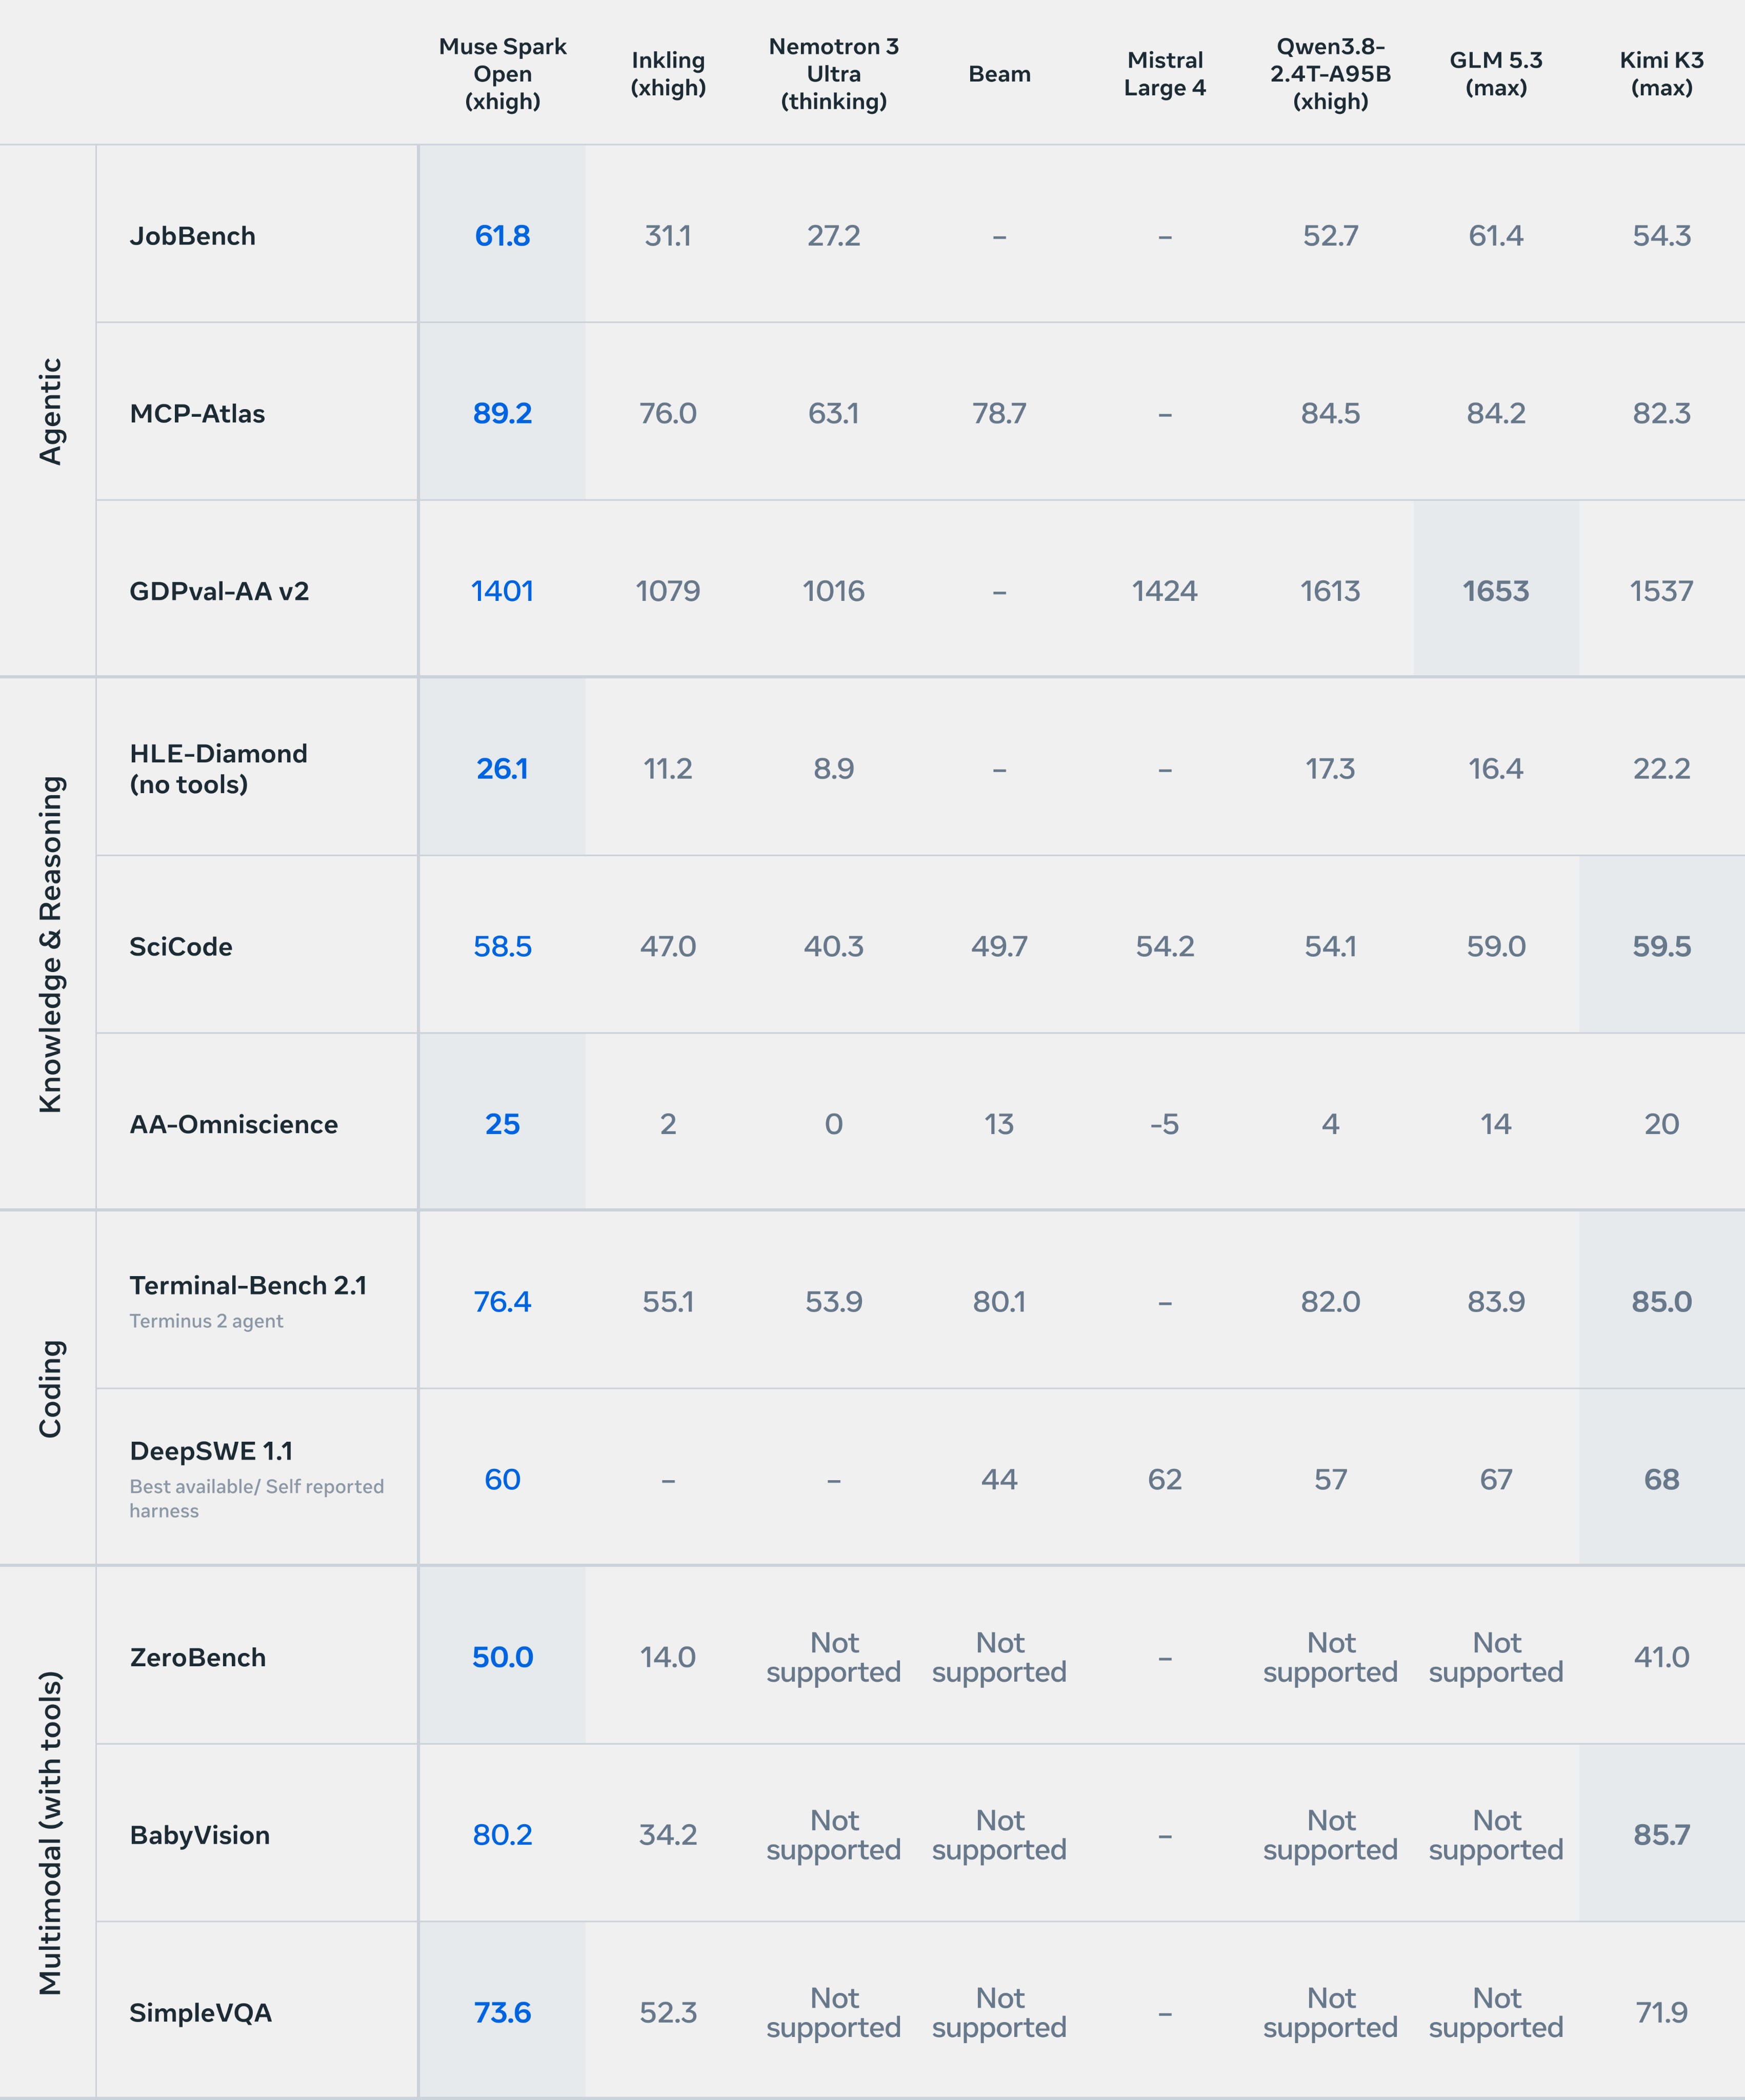
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio

474
1,221
11,531
1,229,555

Superb!

Seven more packs are up
BFCL v3, API-Bank, ARC-Challenge, ARC-Easy, TruthfulQA-817, AIME-2026 and HMMT-Feb-2026.
Want a benchmark added? Drop it in the replies
Install by URL, no Docker, run on your own model:
github.com/TokenTinkererAI/b…
@BenchLocalAI @stevibe
1
1,200
stevibe retweeted

Seven AI models. One DGX Spark. One local workspace. 🔥
Sparkfire puts a full AI suite on your own NVIDIA DGX Spark: read documents, transcribe recordings, translate, generate images, make videos with
sound, sing songs from your lyrics, build mind maps, and chat about all of it with web search. Everything runs locally, side by side, behind one interface.
𝗪𝗵𝗮𝘁 𝗿𝘂𝗻𝘀 𝗼𝗻 𝗼𝗻𝗲 𝗦𝗽𝗮𝗿𝗸 👇
💬 Chat, mind maps, web search · Saluki 27B · 12.7 GiB
📄 Read documents (OCR) · PaddleOCR-VL-1.6 · 5.4 GiB
🎙 Transcription + subtitles · Parakeet-TDT-0.6B-v3 · 1.5 GiB
🌍 Translation, 38 languages · Hy-MT2-1.8B-FP8 · 2.1 GiB
🖼 Image generation · Qwen-Image-2.1-Turbo · 17.5 GiB
🎬 Video with sound · FastH3 · loads on demand
🎵 Songs from your lyrics · YuE2-3B · loads on demand
🔎 Web search · SearXNG, running locally
Everything loaded and idle: 51 of 121 GiB. Video and music load when you use them.
𝗪𝗵𝘆 𝗼𝗻𝗲 𝘄𝗼𝗿𝗸𝘀𝗽𝗮𝗰𝗲
No juggling seven apps, seven interfaces and seven API bills. Every result is a plain file with its history, so one feeds the next: a scanned PDF becomes Markdown, then a translation, a mind map, a summary or a conversation. A generated image becomes the first frame of a video.
𝗪𝗵𝗮𝘁 𝗶𝘁 𝗱𝗼𝗲𝘀
📄 OCR that keeps headings, tables and reading order: 99.9% of words in order on a 20-page test, about 6 s a page
🎙 Transcripts with one line per sentence, SRT and WebVTT subtitles; click a line and the player jumps there
🌍 Translation as you type, or whole documents at once
🖼 Images in about 18 s at 1024×1024, about a minute at 2K, with legible lettering
🎬 5, 8 or 10 s videos with their own soundtrack; 5 s at 480p in about a minute
🎵 48 kHz stereo songs from your lyrics, with an editable score
💬 Chat with your PDFs, images and code, live reasoning, and answers that keep going when you close the tab
🔎 Web search with numbered sources
🔀 Workflows in a node editor, prompt presets, and a gallery with side-by-side compare
📱 Dark and light themes, and it works on your phone
𝗟𝗼𝗰𝗮𝗹 𝗯𝘆 𝗱𝗲𝘀𝗶𝗴𝗻
The models run on your Spark. Your files live in ordinary folders you can read, back up or move. No sign-up, no API keys, no per-token bill.
𝗚𝗲𝘁 𝗶𝘁 𝗿𝘂𝗻𝗻𝗶𝗻𝗴
git clone github.com/MovieMaker93/Spar…
./scripts/start-dgx-spark.sh --accept-model-licenses
A fresh install took 20 minutes and 106 GB of disk.
Open source (Apache 2.0). Sparkfire is a fork of @stevibe 's SparklingKit (github.com/stevibe/Sparkling…), now grown into its own project. Thankou, Steven 🙏
Model licenses apply: FastH3 isn't licensed in the EU, UK, South Korea or US (install with --video-backend none); Qwen-Image and YuE2 are non-commercial.
⭐ github.com/MovieMaker93/Spar…

5
3
13
54,021
stevibe retweeted
New beginning for Windows PCs with local AI is coming soon.
Get ready to run open models with Atomic Chat on @NVIDIARTXSpark
Learn more: blogs.nvidia.com/blog/local-…

Your favorite apps are ready for RTX Spark. ⚡
With systems arriving October 16, see what’s new across apps, games, and local AI tools—including updates for NVIDIA Nemotron, PAIR, Broadcast, and more.

8
14
80
11,994

stevibe retweeted

Introducing Muse Wonder, our new family of frontier models with state of the art performance for personal and professional agentic work.

2,371
3,078
38,847
5,968,882
stevibe retweeted

Introducing Anatomy
Describe a machine in one line. Claude brings it to life.
- Interactive isometric wireframes you can rotate, inspect and explore
- WebGL shaders for fire, water, plasma and more
- Real 3D motion, with individual parts that rotate and move
Install it as an agent skill. Fully open source.

424
1,581
17,931
2,599,905
stevibe retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.
2,112
5,835
43,520
6,672,920
stevibe retweeted

Google AI Pro plans now package premium Colab benefits, landing you A100s with 80GB VRAM (Ultra subs even unlock H100s 🔥).
Here’s what that 80GB headroom unlocks directly in your browser:
✨ Run Gemma 4 31B in bf16
✨ Full fine-tune up to Gemma 4 E4B in bf16
✨ LoRA tune up to Gemma 4 26B A4B in bf16
✨ QLoRA tune up to Gemma 4 31B in bf16

222
787
7,823
1,031,652
stevibe retweeted

Introducing Microsoft-Decision-1, our new model for fast decision-making.
It delivers top performance on structured decision tasks, outperforming both LLMs and other decision models in latency and quality.
We’re already testing it across Microsoft for everything from incident response and quality control to scientific discovery.

708
1,072
11,405
1,697,425
stevibe retweeted

WE GOT IT! .claw incoming!

.Claw cometh!
The winning applicant for .claw top level domain in ICANN’s 2026 round: the OpenClaw Foundation. Huge step in giving our agents a natural home presence.
Congratulations to @davemorin @steipete and the @openclaw team. Looking forward to great things crawling 🦞 across the web soon.
107
77
1,632
203,703
Here are the things I like about GPT:
> It feels like there's no limit when I use Codex
> Its search capability is great
> I always voice-chat with GPT during my commute, sometimes I forget it's an AI. You really want to try that out if you haven't.
> GPT Image is powerful
Opus is good at layout and aesthetics, which is true. So we can just pick the right model for different tasks.
3
13
2,249

