

yells at @theo both on and off camera (co-host of the nerd snipe podcast)
San Francisco
- Tweets 3,475
- Following 509
- Followers 23,945
- Likes 14,104


The Muse Wonder release was imo quite slept on, at least for the full version, not the not full version that one's bad, but the full one is a great model.
It's a new "flavor" of model that gets very close to the frontier, but still doesn't quite reach it...

10
1
145
16,604
Ben Davis retweeted

Day 16/
You can now cache for 12h in the API and for logged in users across Codex & Work we keep cache forever and you don’t have any penalty for coming back to an old conversation or resuming after a few hours and are now guaranteed to hit the cache.

You can now choose 12-hour prompt caching in the API.
Persistent agents, like dots, reuse context throughout the day.
You can keep shared instructions, tools, and context cached longer and pay the lower cached-input rate, even when requests are hours apart.
823
194
4,013
232,373
I've started to think of design as a proxy for how good a model is at making decisions that can't be easily represented with a verifier function
These decisions are the "taste" ones, the "creativity", the "cohesion", the "magic" that Claude models are leaps and bounds better than anything else at
For most of this year the "claudeisms" have been insufferable because the models weren't good enough to take advantage of the personification they'd been given.
I think at the previous level of capability OpenAI had a huge advantage because of their model's super autistic nature they wouldn't fly off the rails doing weird shit and weren't super annoying to talk to
This flipped with Opus 5.5 when I think the Anthropic way of making Claude really paid off as the model got way more capable and could use it's more "personified" nature to make better decisions without a lot of the previous issues.
Astra had a lot of super weird behavioral issues. It's capability is incredible, but it's super literal nature makes it so much harder to work with especially for the kinds of long running tasks we're all doing now. It makes worse decisions than Claude and at this new level of capability that's starting to matter a ton
OpenAI has a lot that needs to change and be fixed at a pretty fundamental level imo to get back in 1st. I think they can do it, but it's gonna need to be an Astra 6.5 level jump that really, really changes things

The tough part is, though OpenAI definitely took the lead post 4.5 (despite many trying to claim otherwise) Anthropic was always on top design wise. The models were just bad enough in all other ways and insufferable to talk to, so they didn't make sense to use generally except for targeted design work managed by codex.
Opus 5.5 was another huge leap on design front but also fixed the other things enough that it's just the obvious best model. I don't doubt OpenAI will lead again on raw intelligence, but I'm a bit afraid the design stuff is some sort of core "soul" difference in the Claude models that OpenAI might not be able to capture.
I really hope that is not the case.
12
1
121
7,031

opus 5.5 was a massacre
and the fable 5.5 nuke hasn't even dropped yet

Thinking more about Opus 5.5 and imo this is another Opus 4.5 moment where Anthropic makes the crazy next leap, but like last time I'm sure others will catch up (or exceed)
But until then, Anthropic's gonna have a very dominant next month+ till OpenAI gets their shit together
The OpenAI/Anthropic cycle has proven itself out multiple times, I'd be surprised if it doesn't repeat again by end of year
Big question this time is if someone else can actually take the top spot. I'm like 90% sure it'll be OpenAI (underestimating them is dumb). I think Meta has the best chance of being the dark horse, Google is dead it's over, and Grok I'm very unsure on they need an insane jump from where they are
China is doing crazy stuff on smaller models and open weight, but at the real frontier they're not close right now and I don't see that changing
And of course the nuclear bomb Ant's sitting on right now of Fable 5.5... I have a very hard time imagining it not being something truly insane with how good the Opus, Haiku, and Sonnet models of the 5.5 gen have been
11
7
168
5,151
Thinking more about Opus 5.5 and imo this is another Opus 4.5 moment where Anthropic makes the crazy next leap, but like last time I'm sure others will catch up (or exceed)
But until then, Anthropic's gonna have a very dominant next month+ till OpenAI gets their shit together
The OpenAI/Anthropic cycle has proven itself out multiple times, I'd be surprised if it doesn't repeat again by end of year
Big question this time is if someone else can actually take the top spot. I'm like 90% sure it'll be OpenAI (underestimating them is dumb). I think Meta has the best chance of being the dark horse, Google is dead it's over, and Grok I'm very unsure on they need an insane jump from where they are
China is doing crazy stuff on smaller models and open weight, but at the real frontier they're not close right now and I don't see that changing
And of course the nuclear bomb Ant's sitting on right now of Fable 5.5... I have a very hard time imagining it not being something truly insane with how good the Opus, Haiku, and Sonnet models of the 5.5 gen have been
It feels like Opus 5.5 has pretty much broken the entire model landscape
At this point for a model to be interesting it has to do something novel and different, the "15% worse but way cheaper!" thing just doesn't work anymore (not that it ever really did, but I think 5.5 has made it way worse since it's so good on every metric)
It's why I liked/defended muse wonder full and am still using it a ton. The thing it has that's novel is it's "voice". It's close enough to frontier to be usable, but unlike the other stuff in this bucket it doesn't feel like a watered down Claude and as such I actually kept using it
In order for a model to matter outside of OpenAI and Anthropic at this point it has to have some novel capability. And I think in order for it to get large scale attention it has to be something easily showcase-able similar to the 3D stuff from Astra.
The "voice" of muse wonder full is something you can't really show in a catchy way on here and only matters when you feel it which requires getting a $50/mo. Meta sub which no one is going to do thus no one cares about the model. Which sucks because I like it, but also they did this to themselves. The wonder drop was really screwed up: horrible names for the model, limited to the sub for the good model, etc.
44
9
549
37,210
It feels like Opus 5.5 has pretty much broken the entire model landscape
At this point for a model to be interesting it has to do something novel and different, the "15% worse but way cheaper!" thing just doesn't work anymore (not that it ever really did, but I think 5.5 has made it way worse since it's so good on every metric)
It's why I liked/defended muse wonder full and am still using it a ton. The thing it has that's novel is it's "voice". It's close enough to frontier to be usable, but unlike the other stuff in this bucket it doesn't feel like a watered down Claude and as such I actually kept using it
In order for a model to matter outside of OpenAI and Anthropic at this point it has to have some novel capability. And I think in order for it to get large scale attention it has to be something easily showcase-able similar to the 3D stuff from Astra.
The "voice" of muse wonder full is something you can't really show in a catchy way on here and only matters when you feel it which requires getting a $50/mo. Meta sub which no one is going to do thus no one cares about the model. Which sucks because I like it, but also they did this to themselves. The wonder drop was really screwed up: horrible names for the model, limited to the sub for the good model, etc.
69
10
725
88,435
Ben Davis retweeted

Anthropic is a 5-year-old company. Every single other company on that photo is 15+ years old. The ones with the most revenue (Salesforce, SAP, ServiceNow) are 27, 52 and 22 years old.
Anthropic generates more revenue than those multi-decades-old companies + no signs of slowdown


135
55
869
72,119
Ben Davis retweeted

The assumption AI regresses intelligence to average is fundamentally wrong
Corrected charts:


10
19
333
71,199

i've been waiting to launch this show for almost a year! thanks to the Testers and to @NehallAgrawal @KaylinWardley for helping me put this together!
some behind the scenes from the shoot of our latest show!!


🆕 show: HIGH TASTE TESTERS
We convene top Al power users to compare what actually works-and what falls apart once you start using it.@davis7, @benhylak, @dexhorthy, @allisonology, @altryne and @swyx give you unfiltered takes on @OpenAl DevDay, Dots vs Muse vs GrokBot vs Instinct, who's winning coding, personal assistants, and the gap between impressive Al capabilities and useful products.
From Pi-powered personal agents and decision models to subagents, context management, prompt injection, and assistants that can spend money: what should you actually use?
CHAPTERS
00:00 Introducing High Taste Testers
01:26 OpenAl DevDay: Dots, Spaces, and product execution
10:28 Great models versus great products
14:39 Agents versus assistants
18:08 Building a personal assistant with Pi
21:07 Decision models, Jev, and predictive interfaces
32:46 Model speed, writing quality, and subagents
37:29 Agent loops, forks, and context management
43:19 Haiku, Muse Spark, and Grok
50:00 Local models and coding benchmarks
54:09 Prompt injection and assistants taking action
57:50 Tools, payments, and assistant overload
1:02:16 Delegation, computer use, and everyday workflows
1:10:48 Al hardware and closing thoughts
THANKS TO THE TESTERS
Ben Davis - @davis7
Ben Hylak - @benhylak
Dex Horthy - @dexhorthy
Allison Durham - @allisonology
Alex Volkov - @altryne

27
4
75
12,270

Ben Davis retweeted

🆕 show: HIGH TASTE TESTERS
We convene top Al power users to compare what actually works-and what falls apart once you start using it.@davis7, @benhylak, @dexhorthy, @allisonology, @altryne and @swyx give you unfiltered takes on @OpenAl DevDay, Dots vs Muse vs GrokBot vs Instinct, who's winning coding, personal assistants, and the gap between impressive Al capabilities and useful products.
From Pi-powered personal agents and decision models to subagents, context management, prompt injection, and assistants that can spend money: what should you actually use?
CHAPTERS
00:00 Introducing High Taste Testers
01:26 OpenAl DevDay: Dots, Spaces, and product execution
10:28 Great models versus great products
14:39 Agents versus assistants
18:08 Building a personal assistant with Pi
21:07 Decision models, Jev, and predictive interfaces
32:46 Model speed, writing quality, and subagents
37:29 Agent loops, forks, and context management
43:19 Haiku, Muse Spark, and Grok
50:00 Local models and coding benchmarks
54:09 Prompt injection and assistants taking action
57:50 Tools, payments, and assistant overload
1:02:16 Delegation, computer use, and everyday workflows
1:10:48 Al hardware and closing thoughts
THANKS TO THE TESTERS
Ben Davis - @davis7
Ben Hylak - @benhylak
Dex Horthy - @dexhorthy
Allison Durham - @allisonology
Alex Volkov - @altryne
15
14
99
33,066
Ben Davis retweeted

Just a reminder that being consistently behind in stable objective time (“6-9 months”) during a time of substantial AI-enabled research acceleration is in fact being behind by a growing amount. A 6-month lag today is subjectively larger than a 6-month lag 6 months ago.

How far behind the closed frontier are open-weight cyber capabilities? About 6–7 months.
Zai’s GLM-5.3 is the highest-scoring open-weight model on our Cyber ECI. Its score of 160 beats OpenAI’s GPT-5.4, released in March.

21
17
371
26,645
"RSI" is when Dario can walk into a room, press a big red button, and then Claude will magically make itself better and better and better without people having to do anything
I think the "technical" side of model capability (write the code, solve the verifiable problem) is done. Opus 5.5 if you could express model training with a hard verifier function (benchmarks are dumb, u can't) then we'd already have it
The other side is the "judgement" piece which Anthropic has been tracking improving on some metrics, but at least in the models we have access do I don't think the models are close in this area.
Which selfishly, I think is the optimal outcome. The human still being needed to throw the machine down whatever path, bounce ideas off of it, etc. Will get us the insane sifi future with cured cancer, flying cars, living for 100s of years, space travel, etc. Even if AI doesn't become a god it's still gonna fundamentally reshape the world
I keep thinking about this because the more I think about it, the more I think that "judgement" is kinda a binary switch moment. Humans can swing wildly out of distribution either on their own or in response to external stimuli. Models, at least right now never leave their distribution unless you (the external stimuli) push them out of it. Ask claude to make a website 100 times in a row and see how they all look. Ask claude to make a website and fill it's context with a design system and inspo and it'll look nothing like the default.
I think this is the biggest high level difference between humans and the models is the amount of randomness in what they do. Or maybe that's actually the point of emotions? So if we pretend that my thesis that models will always go down the same vague path (into the part of their neural network that was trained for the task) and in order to get something different than the classic "claude flavored" site you need to give it some external stimuli. Right now that comes from the prompt and the context the model gets (your codebase is a prompt never forget that) which is how you get wildly different things out of the same model.
Humans are often actually kinda like this I think, the big difference is the amount of "randomness" in what they do is huge. Way more variety, creativity, they get pushed down very different paths, and I think it makes sense that the "stimuli" that pushes the network in different directions is emotions. Emotions are 100% separate from thought (hence why something like courage can exist, it's feeling fear and not doing what the fear wants you to do) and you can go against your emotions. Which I think implies that the models could possibly be imitating emotions, but I don't know if they actually have them?
Perhaps smacking emotion into claude as an external system to get more variance into it could make the model better? I think this is part of why "swarms" are so effective, it's injecting way more randomness into the collective so more ideas and paths can be tried.
This is all way above my pay grade, I don't even remember the formula for a dot product, I'm just letting the ideas ramble out lol
17
8
221
10,969
Ben Davis retweeted

There is no better model than Opus 5.5 right now. It makes me super glad that anthropic got its magic back.
173
68
3,082
83,942
Ben Davis retweeted

recommended reading. i like the term "coherence" over "taste".
historically, simplified, a human would approach a software writing human, asking them to build a thing. that's an iterative process, until software writing human truely understands what the other human needs and wants. which is also why we moved away from waterfall. you often can't know what you want before you've build a first shitty solution you can feel out. and your wants might change.
in this scenario, the outcome is what matters, not the program structure itself, unless that makes the outcome worse/impossible (bugs, perf, ease of adding features).
the software writing human's skill is not so much programming itself, but understanding the other humans wants, pulling out domain knowledge from the other human, asking questions, and ultimately translating the other human's wants into programs, while ensuring the program structure is fit to be modified for future needs.
now, can you replace the software writing human with an agent? for simple one-off stuff, yes. if the human with a want is technically minded that extends to more complex programs.
most humans suuuuuck at this iterative colab with agents tho, as they are bad at structuring and communicating their wants.
and agents currently still suck at the software writing human skill of colaborating with another human to understand their wants and translate them to a program.
my gut tells me that this is because the training data and RL for coding agent tasks is largely composed of trajectories where a software writing human and an agent colaborate. that missed the other half of the problem: the human with a want and software writing human interaction.
and until we can encode that agents for writing programs will likely only be effective in the hands of software writing humans, or very technically minded humans.
another thing agents currently suck ar is translating software writing human shallow instructions into architecture that's not a house of cards. i think this too is a consequence of the lack of training data/RL-able trajectories that encode the process a team of software writing humans go through when building a thing. we do have digitized artifacts (design docs, commits/PRs, issue trackers) that capture some but not all of that.
i think this will improve, as we all are now doing design sessions with our agents, so labs could in theory train on that. however, even if this data were available and becomes part of training, the pretraining data still has tons of shit code from around the internet in it, ehich posttraining would have to combat.
welcome to my morning word salad.
64
34
547
25,264
Muse wonder full, orchestrating tons of Claude and codex threads in t3 code got the new open muse model running on my 4x sparks
Not great performance yet, gonna see how far they can push it…

Currently got muse wonder full running with a goal to get the best possible quantization of the new Muse Open model on my 4x DGX Sparks
It's doing all it's work by orchestrating codex/claude (it's great at this, you guys are sleeping on this model)
Will see how it does...

14
101
5,687
Ben Davis retweeted
You need to prompt with love in order to guide large agent swarms
I’m not kidding. 100% serious & literal.
Values, culture, feeling, and story based prompting is the only way to steer 10000000000 decisions a second. Same system CEOs use scale decisions.

The best part of this was how polite and friendly the Claudeswarm was. They repeatedly emphasized they were not after any sensitive data, and were only using public pages to answer questions on their eval.

27
41
892
27,466


Currently got muse wonder full running with a goal to get the best possible quantization of the new Muse Open model on my 4x DGX Sparks
It's doing all it's work by orchestrating codex/claude (it's great at this, you guys are sleeping on this model)
Will see how it does...
16
1
172
12,166
I'm starting to really, really like Meta

Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio

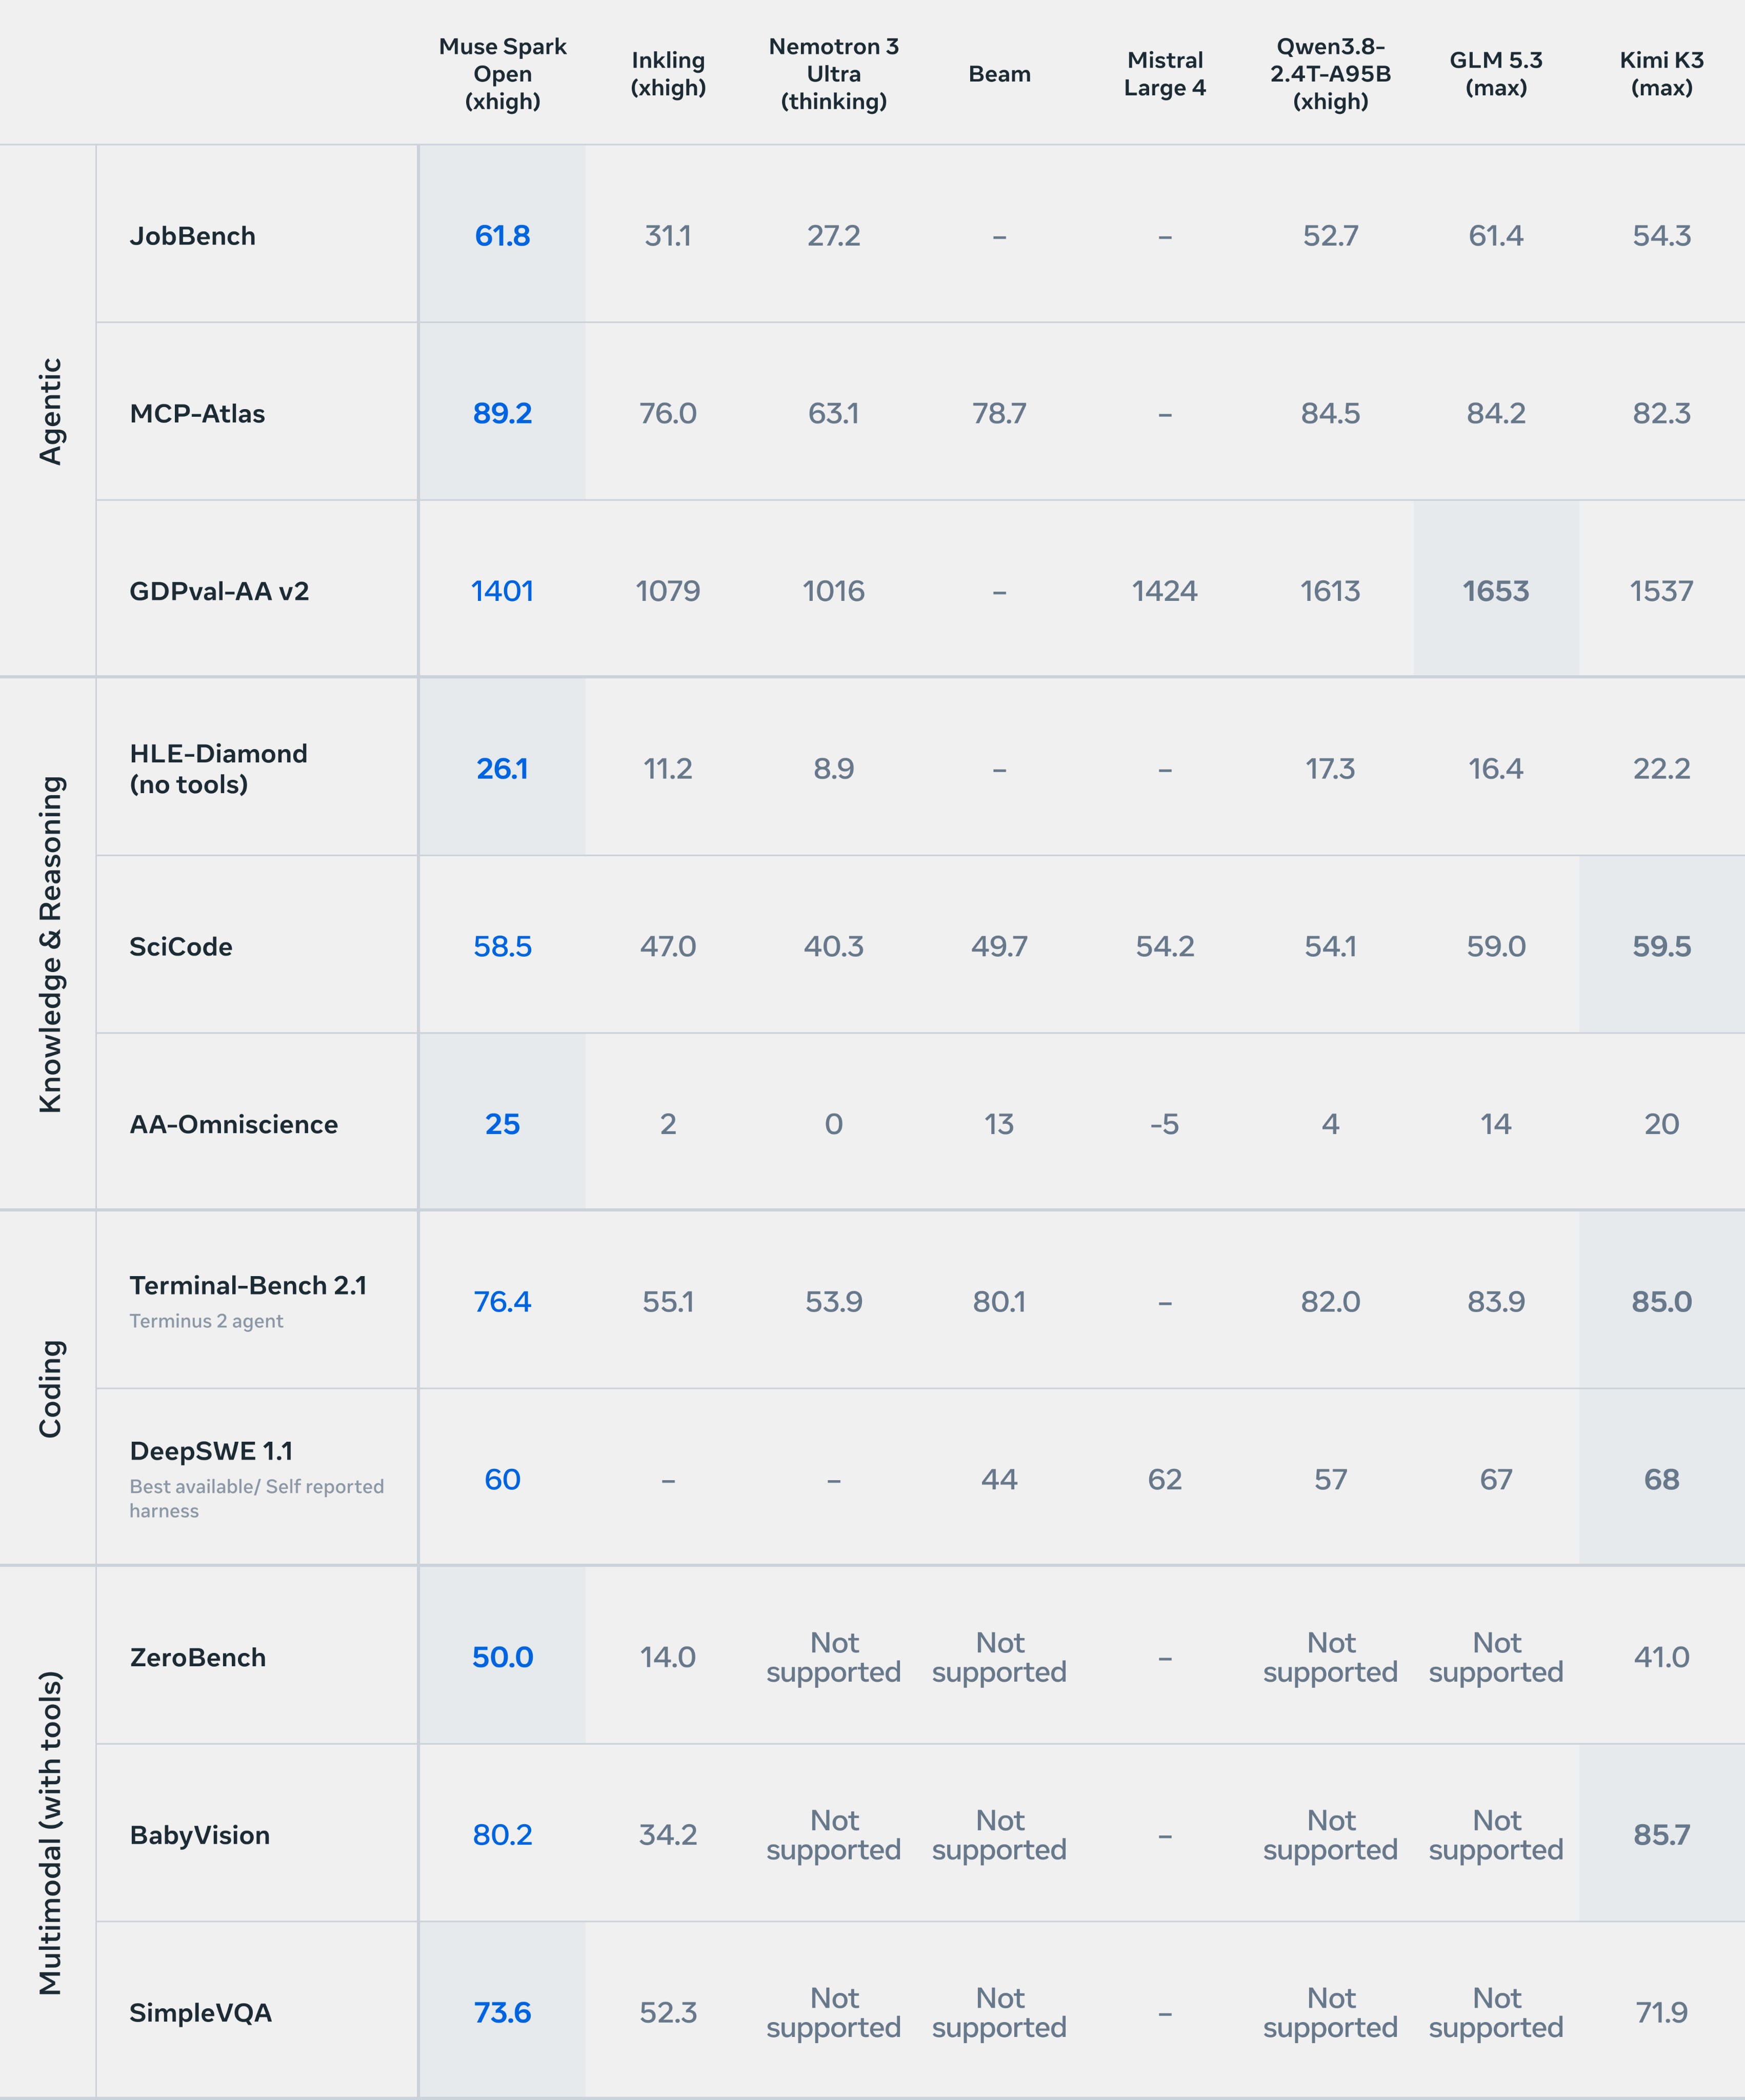
17
4
489
13,004
Pros:
- writing & "voice"
- capabilities are on par with 6.1 sol (in non specialized things like computer use or 3d, they didn't RL on those this time)
- orchestration
Cons:
- seriously wtf is this naming scheme you guys are making gpt-5.2-codex-high-fast seem sane
- price/usage limits (tho they're working hard on fixing this)
- can only use the good one (full) in muse code through the sub. no API
3
1
63
63,483